你将了解到
- Kimi K3 是什么,它有何不同?
- 底层架构:KDA、Attention Residuals 与 Stable LatentMoE
- 如何使用推理强度、流式输出、工具、视觉和 1M 上下文?
- 如何从第一次 API 调用走向生产环境?
- Kimi K3 在编码和智能体基准测试上与前沿模型相比如何?
- Kimi K3 在 Together AI 上的价格是多少?
Kimi K3 是 Moonshot AI 迄今能力最强的模型:参数量 2.8 万亿,也是全球首个 3 万亿参数级别的开源模型。它面向前沿智能任务设计,例如长周期编码、端到端知识工作和深度推理。它同时也是首个能与 GPT 5.6 Sol 和 Claude Fable 5 同档竞争的开放权重模型,Together AI 正与 Moonshot 团队直接合作来提供该模型的服务。
已发布的最大开放权重模型
Kimi 团队对规模化投入极深,成果也有目共睹:在 2025 年 7 月至 2026 年 7 月的十二个月里,有九个月是 Kimi 模型刷新了开源模型的规模上限。K3 拥有 2.8 万亿参数,是迄今发布的最大开放权重模型。
现已上线
在 Together AI 上运行 Kimi K3
完整 1M 上下文、自动前缀缓存、兼容 OpenAI 的 API,由美国本土基础设施提供服务。
打开 Playground
底层架构
K3 的骨干由两项架构更新构成,二者都旨在让信息更顺畅地在更长的序列中流动、并更深入地传入网络内部:
- Kimi Delta Attention(KDA):一种混合线性注意力机制,为在超长上下文上扩展注意力提供了高效基础。这是首个支持 1M 上下文长度的 Kimi 模型。
- Attention Residuals(AttnRes):沿模型深度有选择地检索表征,而不是均匀地累积它们。
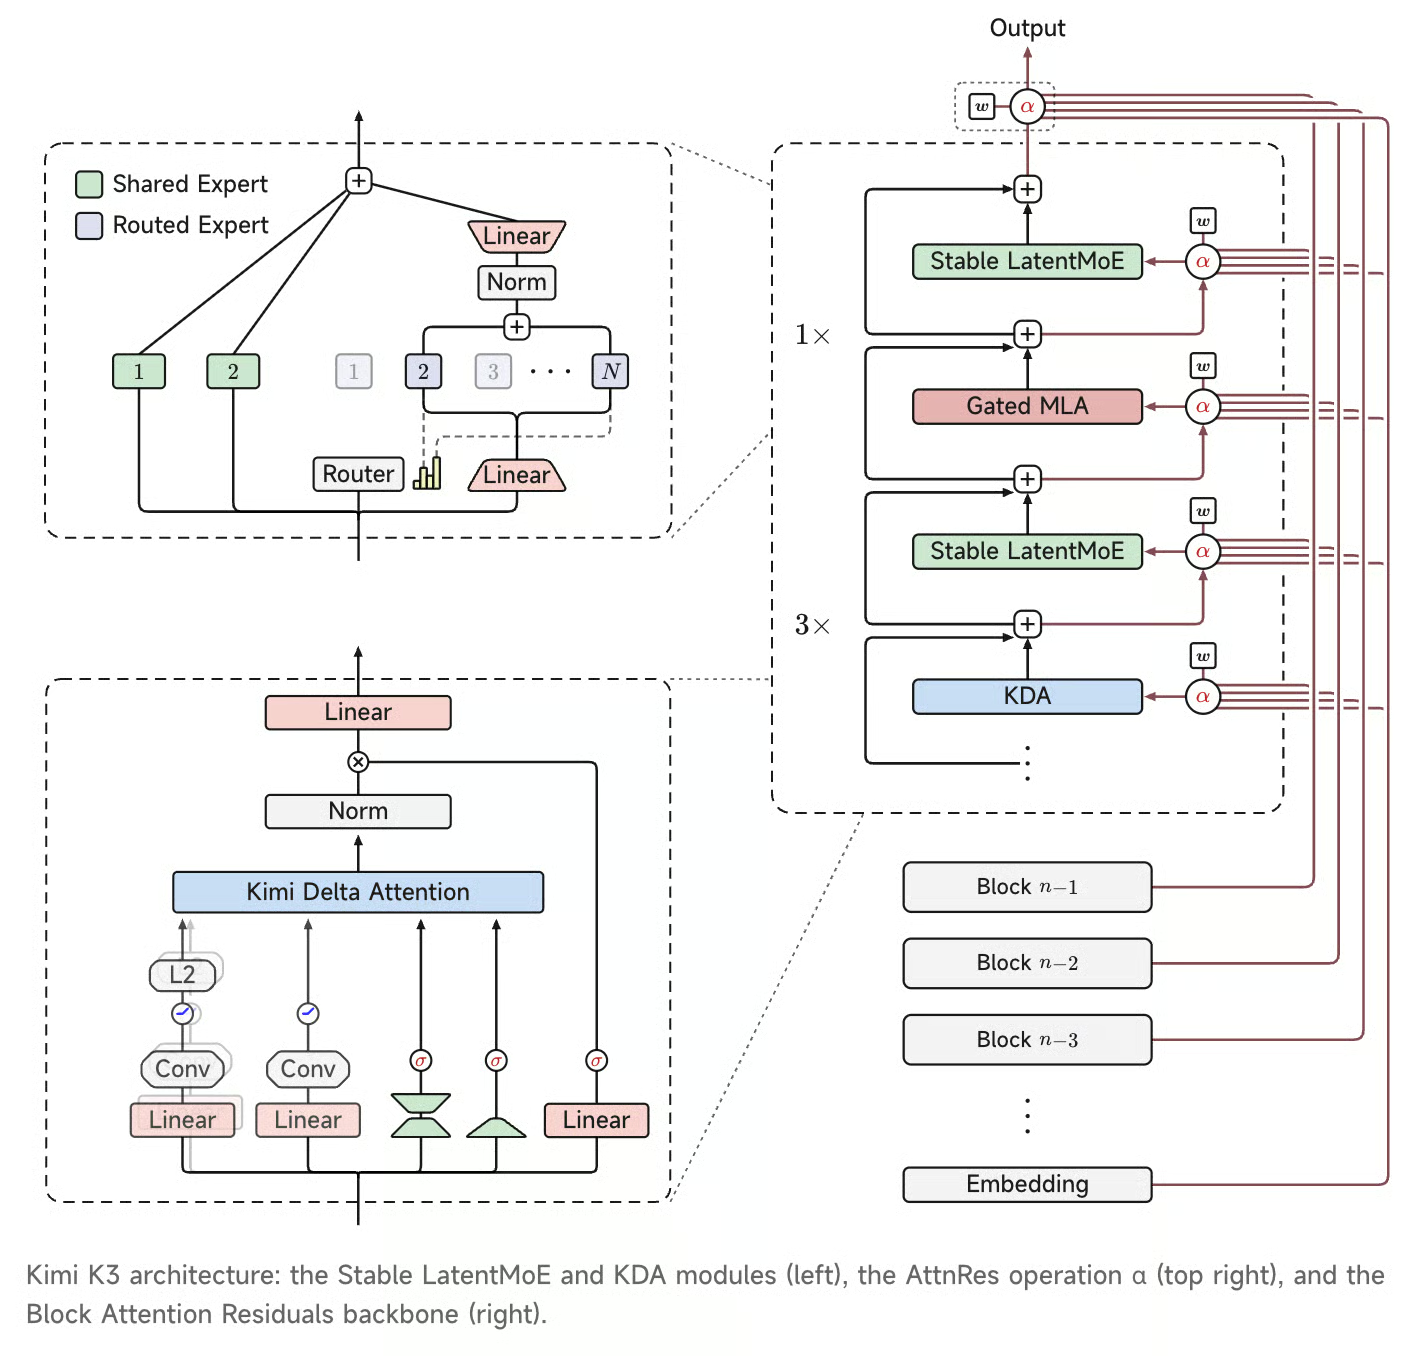
在此之上,Moonshot 通过 Stable LatentMoE 框架进一步提升了混合专家(Mixture-of-Experts)的稀疏度,在 896 个专家中高效激活 16 个。在这样的稀疏程度下,每个 token 仅激活约 2% 的专家,路由与优化成为首要难题,因此多项配套技术共同保障了 2.8T 规模下的稳定训练:
- Quantile Balancing:直接根据路由分数的分位数确定专家分配,省去了启发式更新和一个敏感的均衡超参数。
- Per-Head Muon:将 Muon 优化器扩展为对各注意力头独立优化,使大规模学习更具适应性。
- Sigmoid Tanh Unit(SiTU):改进激活控制。
- Gated MLA:提升注意力的选择性。
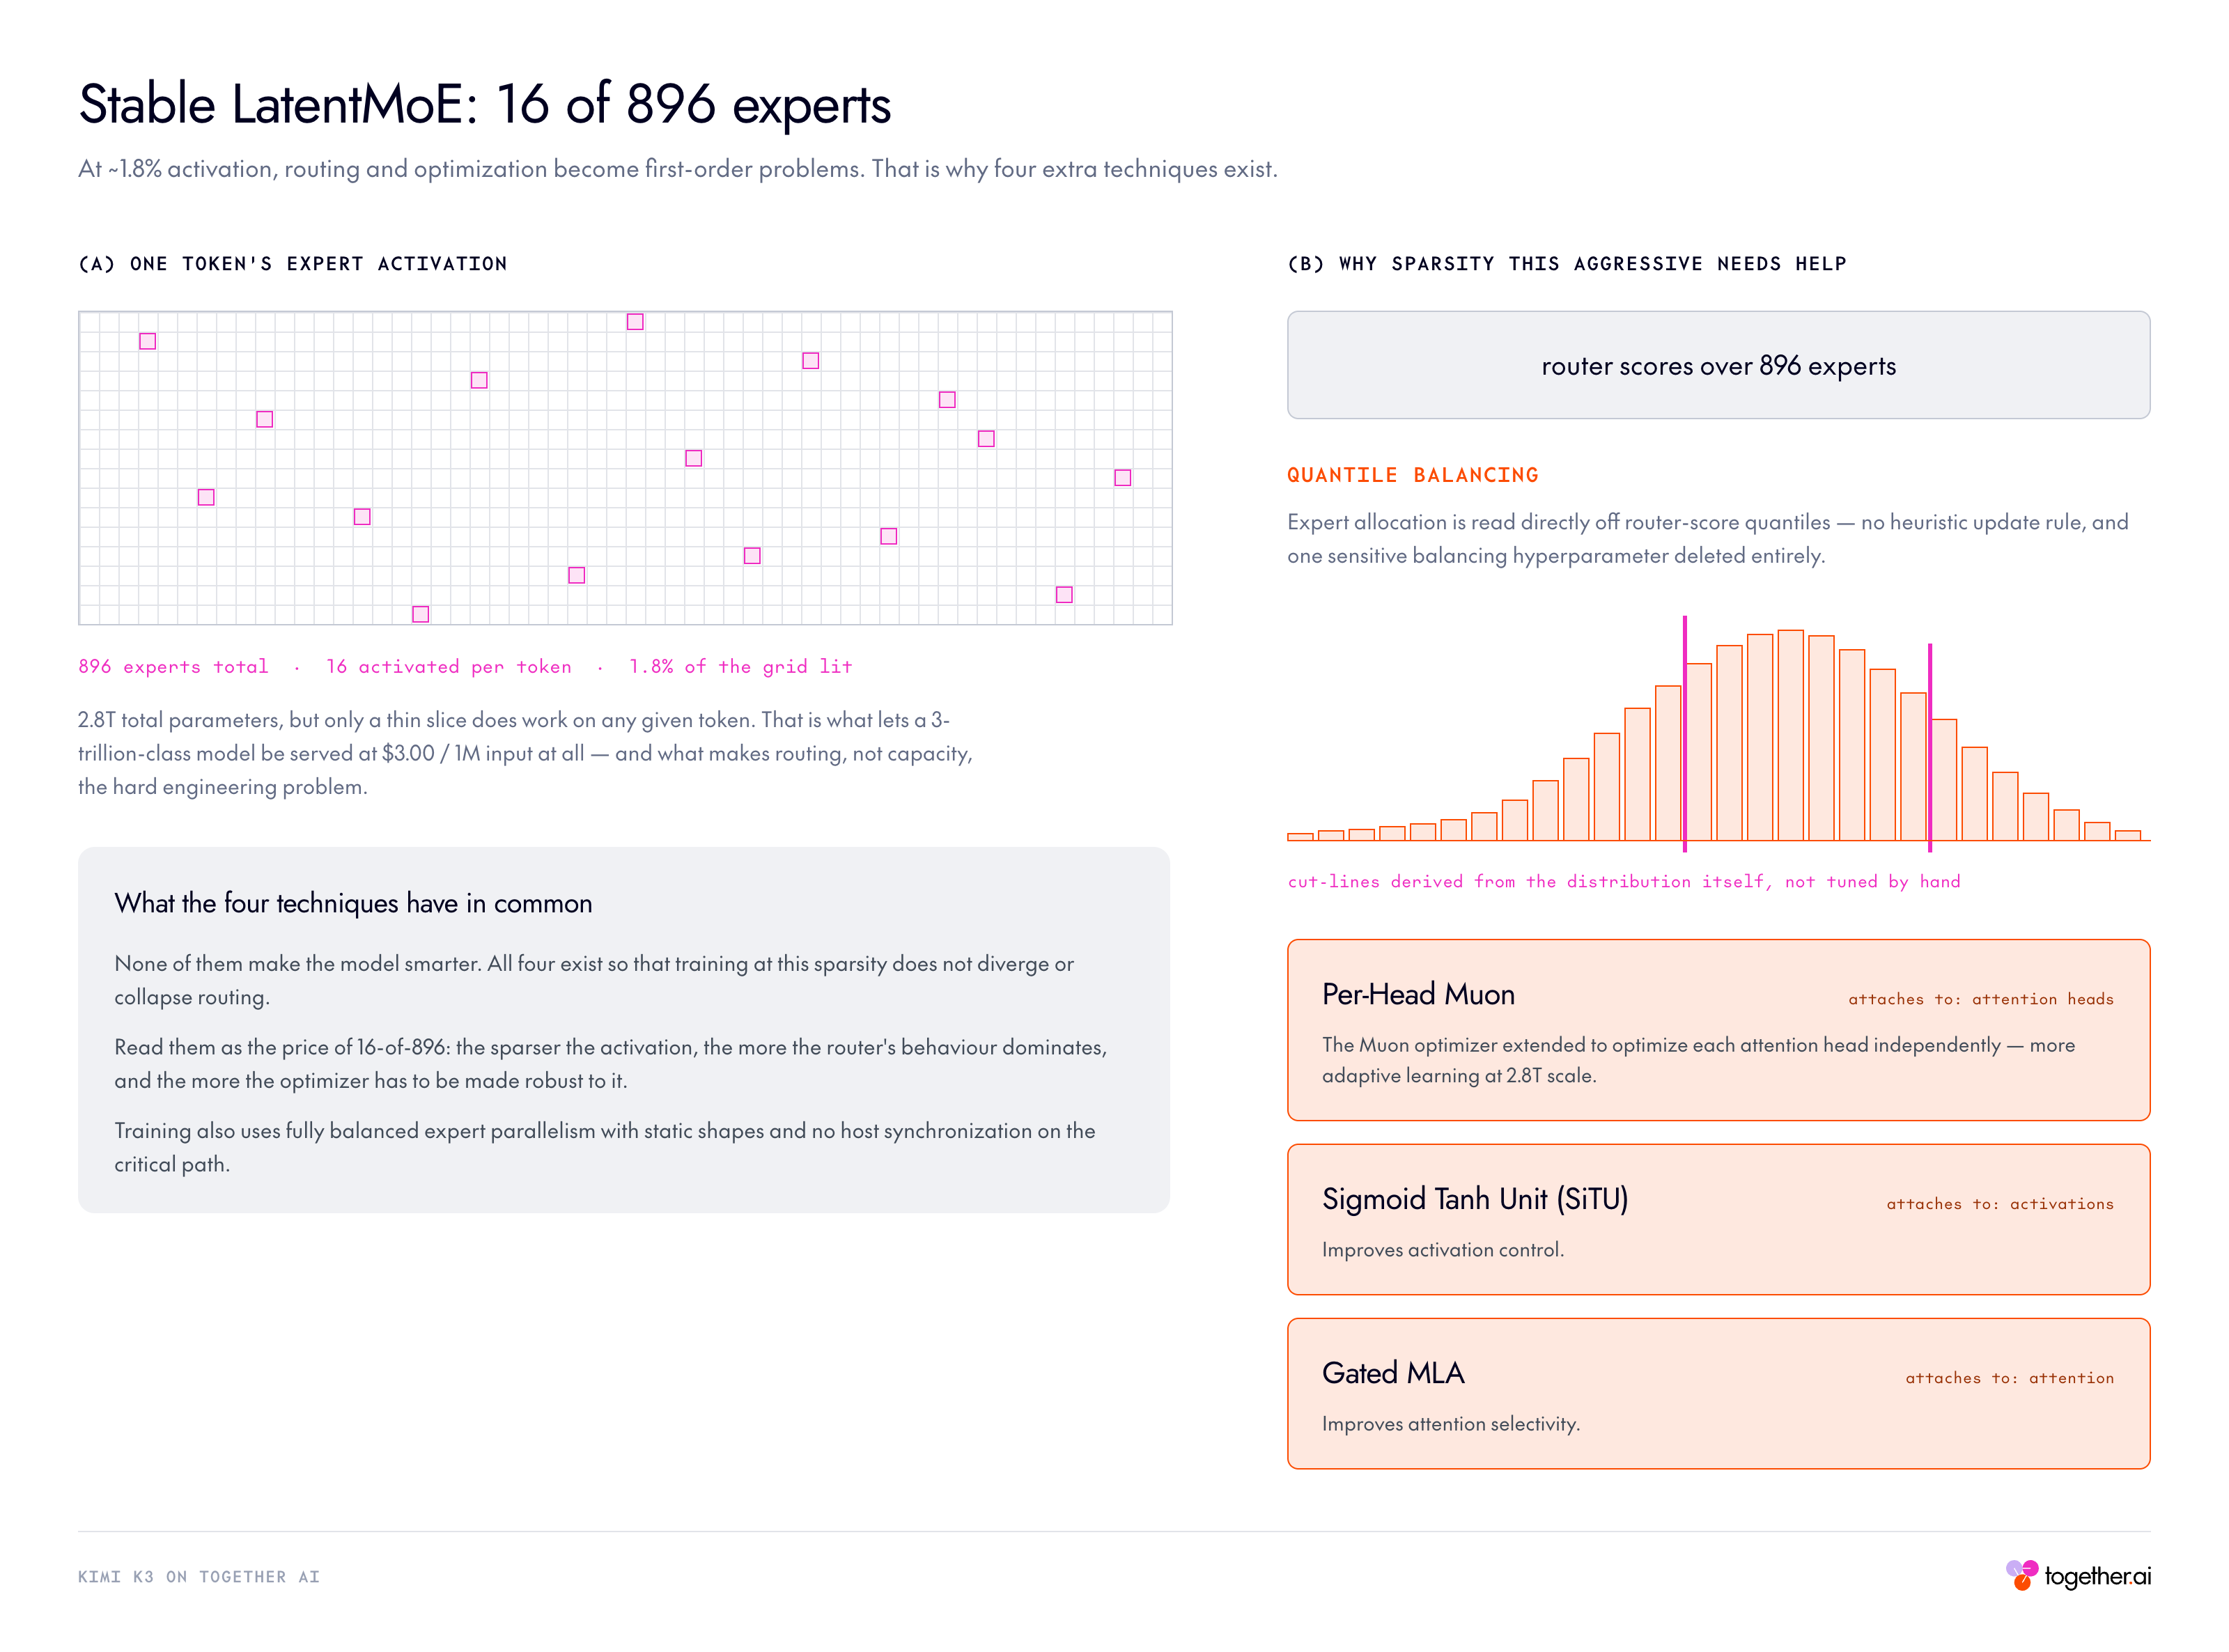
如何在 Together AI 上使用 Kimi K3
该 API 兼容 OpenAI。下面的代码片段以 Together AI 为目标,使用官方 Together Python SDK。
python3 -m pip install --upgrade 'together>=2.0.0'
import os
from together import Together

MODEL = "moonshotai/Kimi-K3"

client = Together(
    api_key=os.environ["TOGETHER_API_KEY"],
)

completion = client.chat.completions.create(
    model=MODEL,
    messages=[{"role": "user", "content": "Introduce Kimi K3 in one sentence."}],
    max_tokens=130_000,
)
print(completion.choices[0].message.content)
思考强度
K3 可通过顶层的 reasoning_effort 字段配置,支持三档:low、high 和 max,默认为 max。在 Together 上,也可以通过标准的 reasoning={"enabled": False} 开关关闭思考。
# Adjust depth: "low" | "high" | "max"
completion = client.chat.completions.create(
    model=MODEL,
    reasoning_effort="max",
    messages=[{"role": "user", "content": "Prove that the square root of 2 is irrational."}],
    max_tokens=8192,
)

# Instant mode, no thinking tokens billed at all
fast = client.chat.completions.create(
    model=MODEL,
    messages=[{"role": "user", "content": "What is the capital of France?"}],
    reasoning={"enabled": False},
    max_tokens=256,
)
流式输出
流式响应会分别返回 reasoning_content(思考轨迹)和最终答案 content 的增量。
stream = client.chat.completions.create(
    model=MODEL,
    messages=[{"role": "user", "content": "Explain why the sky is blue."}],
    max_tokens=4096,
    stream=True,
)

in_answer = False
for chunk in stream:
    if not chunk.choices:
        continue
    delta = chunk.choices[0].delta
    thinking = getattr(delta, "reasoning_content", None) or getattr(delta, "reasoning", None)
    if thinking:
        print(thinking, end="", flush=True)
    if delta.content:
        if not in_answer:
            print("\n--- answer ---")
            in_answer = True
        print(delta.content, end="", flush=True)
视觉输入
可以提供多张图像作为输入。Moonshot 还发布了一个视觉推理基准测试 Perception Bench。
import base64
from pathlib import Path

# Option A: pass an image by URL
IMAGE_URL = "https://raw.githubusercontent.com/pytorch/pytorch/main/docs/source/_static/img/pytorch-logo-dark.png"
image_content = {"type": "image_url", "image_url": {"url": IMAGE_URL}}

# Option B: pass a local image as base64 (uncomment to use)
# image_data = base64.b64encode(Path("image.png").read_bytes()).decode()
# image_content = {"type": "image_url",
#                  "image_url": {"url": f"data:image/png;base64,{image_data}"}}

completion = client.chat.completions.create(
    model=MODEL,
    max_tokens=2048,
    messages=[{
        "role": "user",
        "content": [
            image_content,
            {"type": "text", "text": "Describe this image."},
        ],
    }],
)
视觉限制:
- 图像数量没有限制,但整个请求体必须小于 100 MB。
- 建议的图像上限:4K(4096x2160)。更高的分辨率会增加处理时间和 token 消耗,却不会提升理解效果。
- token 成本随分辨率增长。
结构化输出
使用 response_format 配合 json_schema 以及 strict: true,来约束最终的 message.content。
import json

completion = client.chat.completions.create(
    model=MODEL,
    max_tokens=4096,
    messages=[{"role": "user", "content": "Ada Lovelace was 36 years old."}],
    response_format={
        "type": "json_schema",
        "json_schema": {
            "name": "person",
            "strict": True,
            "schema": {
                "type": "object",
                "properties": {"name": {"type": "string"}, "age": {"type": "integer"}},
                "required": ["name", "age"],
                "additionalProperties": False,
            },
        },
    },
)

person = json.loads(completion.choices[0].message.content)
# -> {'name': 'Ada Lovelace', 'age': 36}
如果只需要语法合法的 JSON,在 Together 上也可以使用较宽松的 {"type": "json_object"} 模式。无论哪种方式,都要把 max_tokens 设得足够大:整个思考轨迹会在第一个受 schema 约束的 token 输出之前耗尽,因此上限过紧会截断 JSON,而不是截断推理。
Tools 与 tool_choice
K3 保留了标准的 tool-choice 约束。标准循环如下:在 tools 中声明函数;当模型返回 tool_calls 时,把完整的 assistant 消息追加到历史中,再为每次调用各追加一条带有对应 tool_call_id 的 tool 消息,然后再次调用。首轮可使用 tool_choice="required" 强制至少发起一次工具调用,之后再切回 "auto"。更改 tool_choice 不会使前缀缓存失效。
import json

tools = [{
    "type": "function",
    "function": {
        "name": "get_weather",
        "description": "Get the current weather for a city.",
        "parameters": {
            "type": "object",
            "properties": {
                "city": {"type": "string", "description": "City name, e.g. Paris"},
                "unit": {"type": "string", "enum": ["celsius", "fahrenheit"]},
            },
            "required": ["city"],
            "additionalProperties": False,
        },
    },
}]

def get_weather(city, unit="celsius"):
    return {"city": city, "temperature": 21, "unit": unit, "conditions": "sunny"}

messages = [{"role": "user", "content": "What's the weather in Paris?"}]
choice_mode = "required"          # force a tool call on turn one

for _ in range(5):
    response = client.chat.completions.create(
        model=MODEL,
        messages=messages,
        tools=tools,
        tool_choice=choice_mode,
        max_tokens=8192,
    )
    choice = response.choices[0]
    message = choice.message

    # Append the COMPLETE assistant message, thinking trace included.
    messages.append(message.model_dump(exclude_none=True))

    if choice.finish_reason != "tool_calls" or not message.tool_calls:
        print(message.content)
        break

    for call in message.tool_calls:
        try:
            args = json.loads(call.function.arguments)
        except json.JSONDecodeError:
            args = {}
        messages.append({
            "role": "tool",
            "tool_call_id": call.id,
            "content": json.dumps(get_weather(**args)),
        })

    choice_mode = "auto"          # hand control back after the forced turn
动态工具加载
你可以把完整的工具定义(完整名称、描述和参数)放进一条带有 tools 字段、且不含 content 的 system 消息中。该工具从这条消息所在位置起开始可用。
关键规则:
- 动态声明所用的格式与顶层 tools 字段完全相同。
- 它们按请求生效,服务器不会保留,因此需要你自己在后续请求的历史中保留这条消息。保留它既能保住工具的可用性,也能保住缓存前缀;丢弃它则意味着模型无法再调用该工具,并且变化后的前缀可能无法命中缓存。
- 在 messages 末尾追加动态声明不会影响已缓存的前缀;而删除或修改更早的声明,可能会让变更点之后的缓存命中受损。
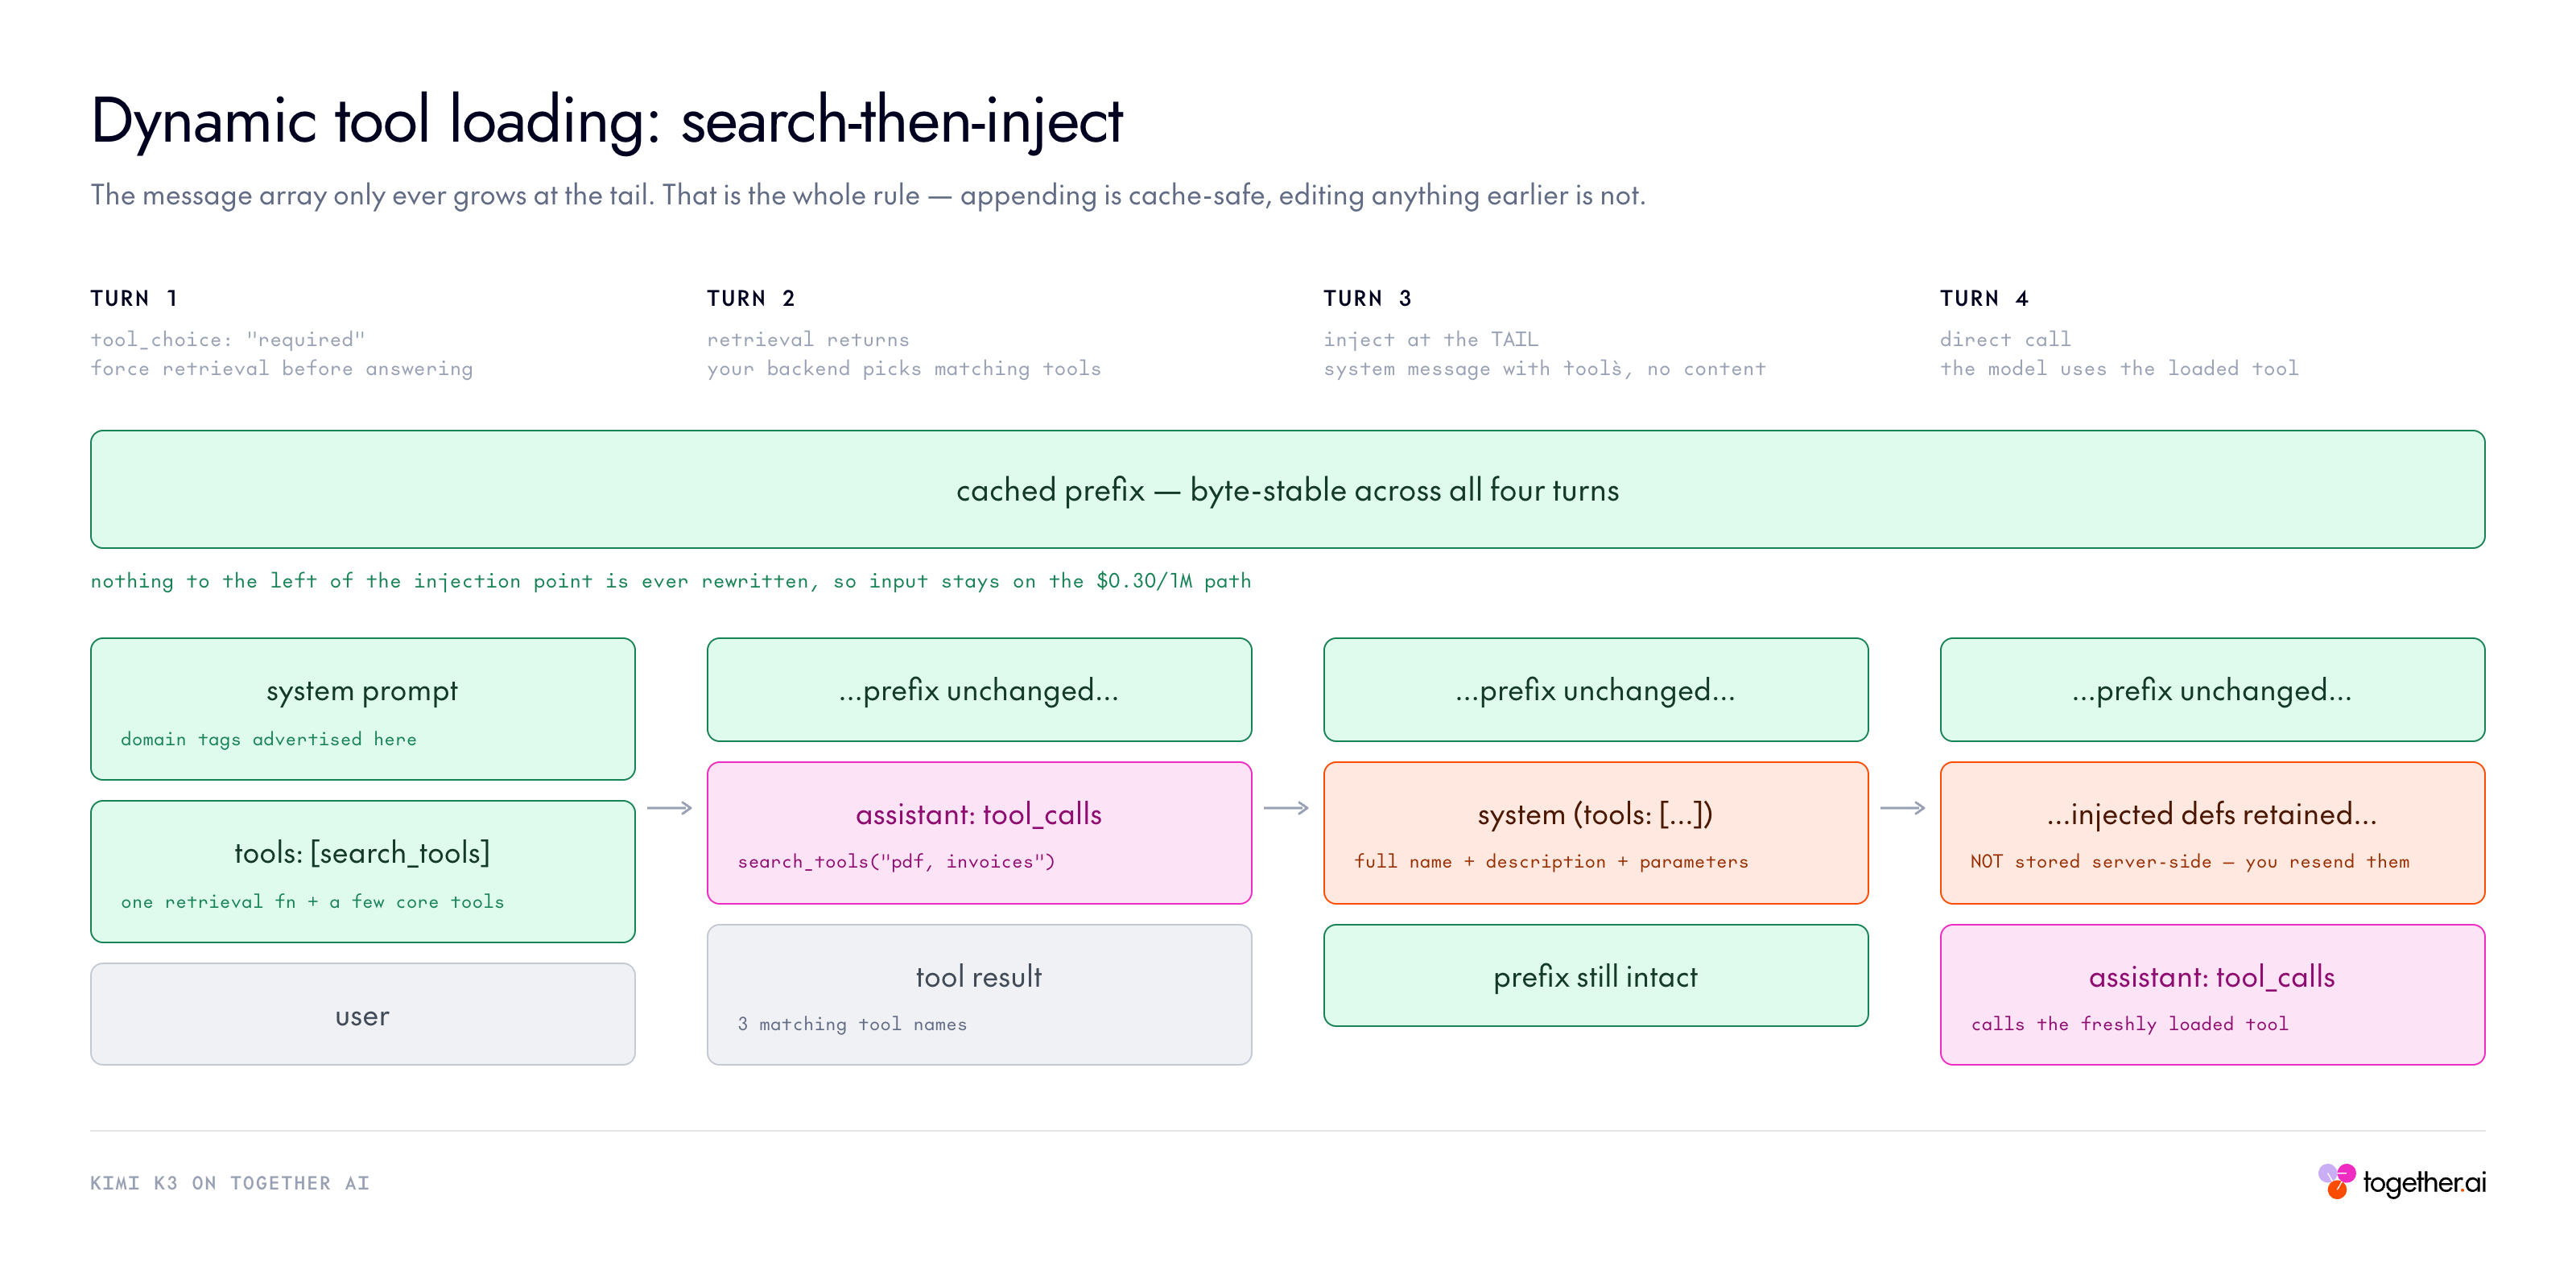
面向大型工具目录的推荐模式:
- 对话开始:只声明一个 search_tools 函数(由你的后端实现)和少量核心工具,并在系统提示词中列出可检索的领域标签。
- 第一轮:设置 tool_choice: "required",强制模型先检索再回答。
- 按需注入:根据检索结果,通过 system 消息插入匹配工具的完整定义。
- 直接调用:模型在后续生成中使用已加载的工具。
- 成本权衡:在对话开始前就确定 reasoning_effort。
代码示例:
CATALOG = {
    "convert_currency": {
        "type": "function",
        "function": {
            "name": "convert_currency",
            "description": "Convert an amount from one currency to another.",
            "parameters": {
                "type": "object",
                "properties": {
                    "amount": {"type": "number"},
                    "from_currency": {"type": "string"},
                    "to_currency": {"type": "string"},
                },
                "required": ["amount", "from_currency", "to_currency"],
                "additionalProperties": False,
            },
        },
    },
}

search_tools = {
    "type": "function",
    "function": {
        "name": "search_tools",
        "description": "Search the tool catalog. Tags: finance, travel, files.",
        "parameters": {
            "type": "object",
            "properties": {"query": {"type": "string"}},
            "required": ["query"],
            "additionalProperties": False,
        },
    },
}

messages = [{"role": "user", "content": "Convert 100 USD to EUR."}]

# 1. Force retrieval before answering.
first = client.chat.completions.create(
    model=MODEL, messages=messages, tools=[search_tools],
    tool_choice="required", max_tokens=8192,
)
call = first.choices[0].message.tool_calls[0]
messages.append(first.choices[0].message.model_dump(exclude_none=True))
messages.append({"role": "tool", "tool_call_id": call.id,
                 "content": json.dumps(list(CATALOG))})

# 2. Inject matching definitions at the TAIL. `tools` field, NO content.
messages.append({"role": "system", "tools": [CATALOG["convert_currency"]]})

# 3. The model calls the freshly loaded tool directly.
second = client.chat.completions.create(
    model=MODEL, messages=messages, tools=[search_tools],
    tool_choice="auto", max_tokens=8192,
)
print(second.choices[0].message.tool_calls)
# -> convert_currency({"amount":100,"from_currency":"USD","to_currency":"EUR"})
1M 上下文与自动缓存
Together 支持完整的 1M 上下文长度,上下文缓存是自动的。请让你的长前缀(系统提示词、知识库、代码仓库内容)在各次请求间保持字节级稳定,这样后续调用才能命中缓存。Moonshot 建议把固定的大块上下文(知识文档)放在 messages 数组的最开头、system 消息之前,然后在其后追加问题和回复。
def _get(obj, key, default=None):
    if obj is None:
        return default
    return obj.get(key, default) if isinstance(obj, dict) else getattr(obj, key, default)

usage = completion.usage
reasoning_tokens = _get(_get(usage, "completion_tokens_details"), "reasoning_tokens", 0)
cached_tokens = _get(_get(usage, "prompt_tokens_details"), "cached_tokens",
                     _get(usage, "cached_tokens", 0))

print(f"prompt={usage.prompt_tokens} cached={cached_tokens} "
      f"completion={usage.completion_tokens} thinking={reasoning_tokens}")
# -> prompt=86 cached=64 completion=133 thinking=111
采样参数
采样参数是固定的,请求中应省略它们。模型是用这些参数训练的,不支持设置其他值:
- temperature = 1.0
- top_p = 0.95
- n = 1
- presence_penalty = 0
- frequency_penalty = 0
保留思考
K3 是以保留思考历史的模式训练的,因此思考轨迹就是下一轮所依赖的状态。请按下面的方式保留上一轮的思考 token,并转发给后续轮次。
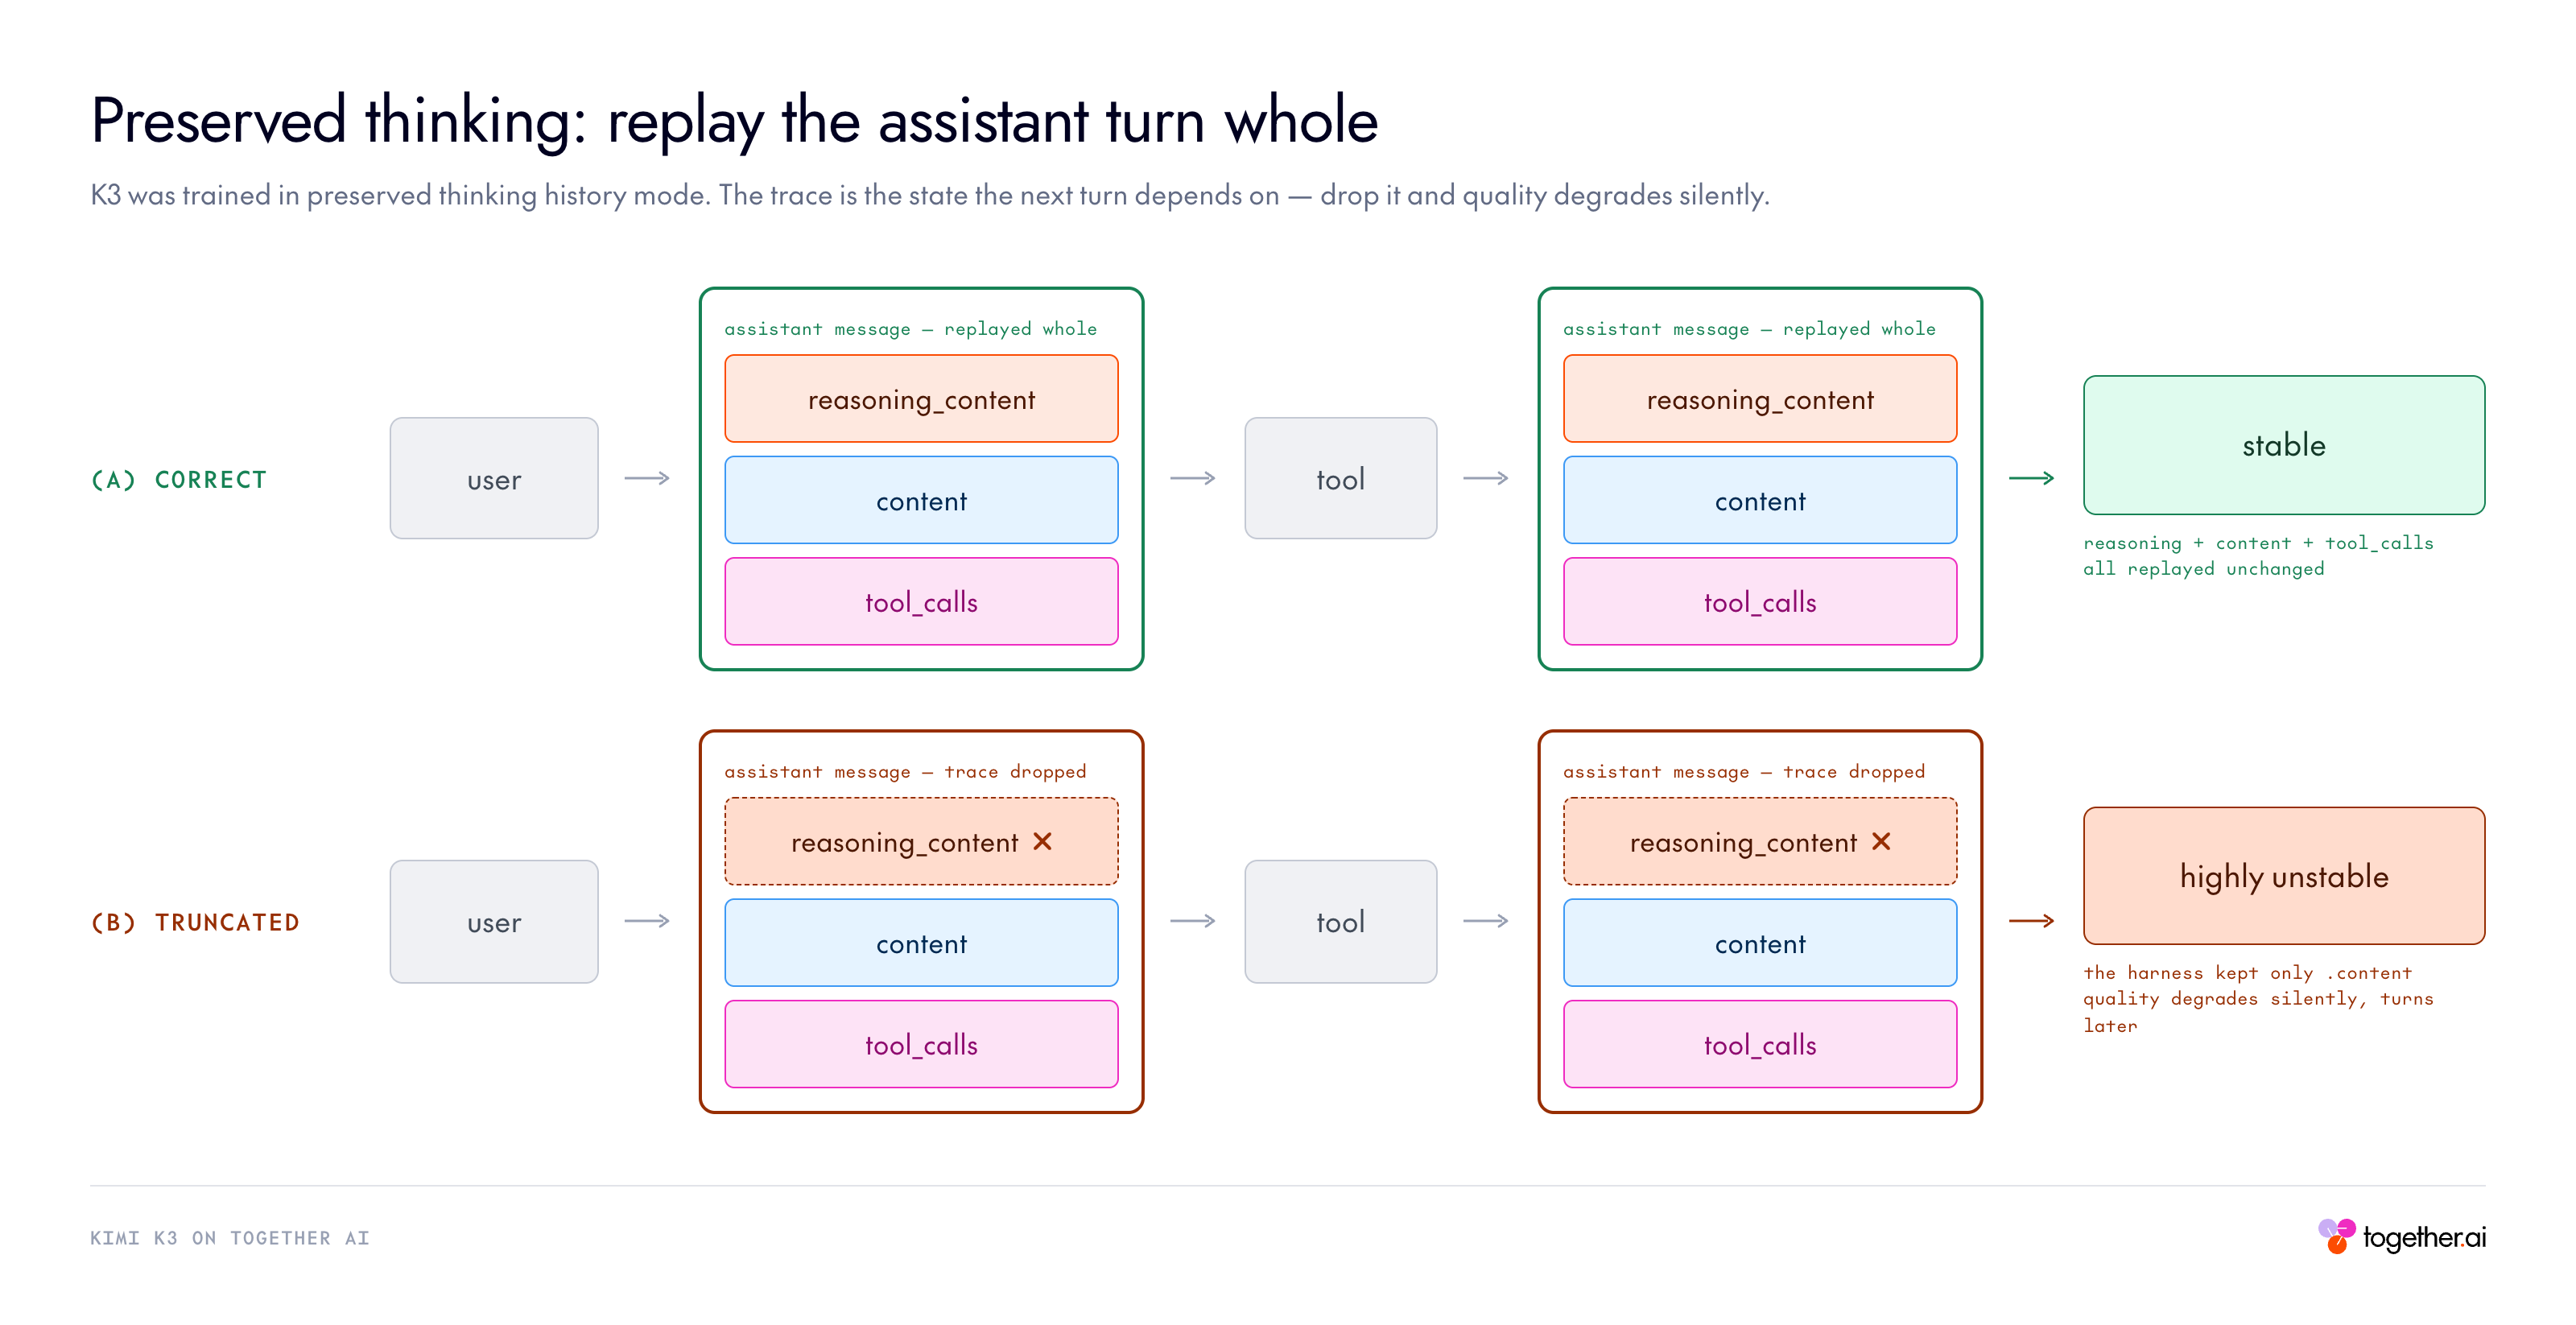
SECRET = "48213"
TRACE  = "For the session codeword I will use 48213. Committing to 48213 as the codeword."

messages = [
    {"role": "user", "content": "Pick a 5-digit codeword for our session and remember it. "
                                "Reply with exactly: OK"},
    # The trace rides along on the assistant turn. No flag needed.
    {"role": "assistant", "content": "OK", "reasoning_content": TRACE},
    {"role": "user", "content": "What codeword did you pick? Reply with just the number."},
]

completion = client.chat.completions.create(
    model=MODEL,
    messages=messages,
    max_tokens=4000,
    chat_template_kwargs={"preserve_thinking": True}
)
print(completion.choices[0].message.content)   # -> 48213
去掉 reasoning_content 那一行,同样的调用每次都会给出一个全新编造的不同数字。在实际代码中,你不会手写这段轨迹,而是回放模型产生的内容,也就是工具循环里的那行单行代码:
# Turn 1 - let K3 think.
first = client.chat.completions.create(
    model=MODEL,
    messages=[{"role": "user", "content": "Pick a random 5-digit number and commit to it. "
                                          "Do not tell me. Reply with exactly: OK"}],
    max_tokens=4000,
)

# Replay the assistant turn WHOLE. model_dump keeps reasoning_content alongside content.
history = [
    {"role": "user", "content": "Pick a random 5-digit number and commit to it. "
                                "Do not tell me. Reply with exactly: OK"},
    first.choices[0].message.model_dump(exclude_none=True),
    {"role": "user", "content": "What number did you pick? Reply with just the number."},
]

second = client.chat.completions.create(model=MODEL, messages=history, max_tokens=4000)
print(second.choices[0].message.content)
Kimi K3 定价
Kimi K3 按 token 计价,并设有缓存命中的输入档位,奖励稳定的前缀:
Kimi K3 定价
| 档位 | 每 1M token 价格 |
|---|---|
| 输入(缓存命中) | \$0.30 |
| 输入(缓存未命中) | \$3.00 |
| 输出 | \$15.00 |
上下文窗口:1,048,576 token(1M)。思考 token 按输出计费。
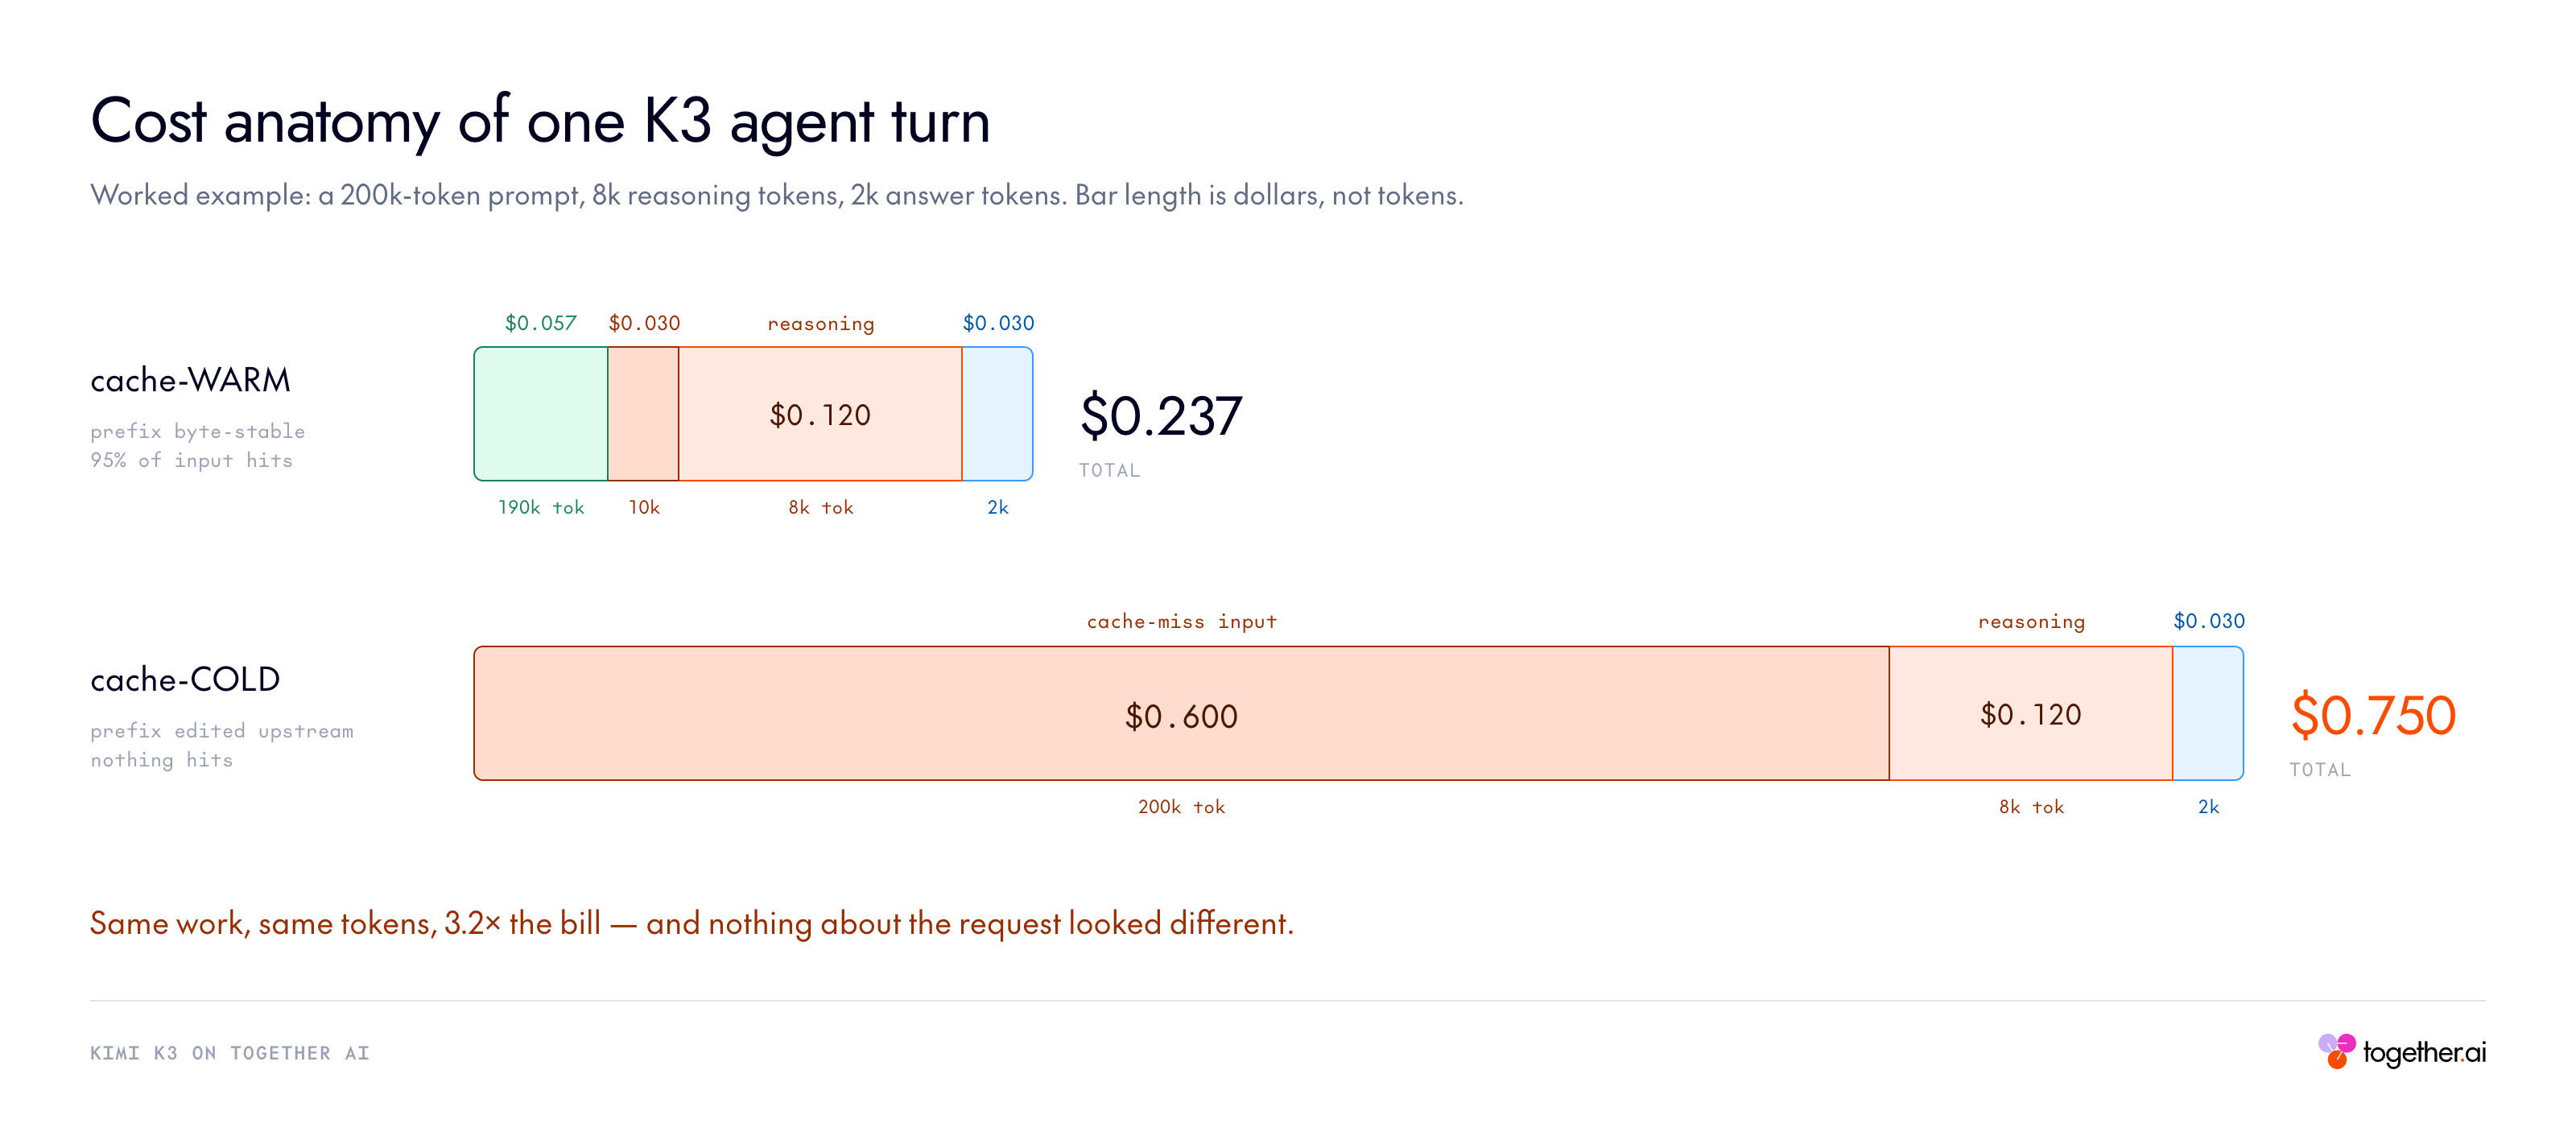
需要牢记的两点成本因素:
- 缓存是你的杠杆。在编码工作负载中命中率 >90% 时,有效输入成本会趋近 \$0.30 的下限,但前提是保持前缀稳定。重构更早的消息或工具声明会破坏缓存。
- 推理按输出计费,且可以调节。思考 token 属于输出 token,价格为 \$15/M,且思考无法被完全关闭,但 reasoning_effort 现在有三档。max 仍是默认值,所以从不设置该字段的流水线,每次调用都在支付最高的推理费用,连那些简单的调用也不例外。
Kimi K3 基准测试
在整套评测中,Kimi K3 取得了前沿水平的成绩。它在多项编码和智能体基准测试(SWE Marathon、BrowseComp、DeepSearchQA、AutomationBench、OmniDocBench)上领先,在其他基准上则与最强的专有模型保持竞争力,同时明显优于受测的另一款开源模型 GLM-5.2。在少数基准上它落后于 Claude Fable 5 和 GPT 5.6 Sol,这与 Moonshot 自身对该模型的定位一致。
以下所有 Kimi K3 结果均使用 max 推理强度。
Kimi K3 基准测试
推理强度:max
| 基准测试 | Kimi K3 max | Claude Fable 5 max,含回退 | GPT 5.6 Sol max | Claude Opus 4.8 max | GLM-5.2 max |
|---|---|---|---|---|---|
| 编码 | |||||
| DeepSWE | 67.5 | 70.0 | 73.0 | 59.0 | 46.2 |
| Program Bench | 77.8 | 76.8 | 77.6 | 71.9 | 63.7 |
| Terminal Bench 2.1 | 88.3 | 84.6 | 88.8 | 84.6 | 82.7 |
| FrontierSWE | 81.2 | 86.6 | 71.3 | 66.7 | 67.3 |
| SWE Marathon | 42.0 | 35.0 | 39.0 | 40.0 | 13.0 |
| PostTrain Bench | 36.6 | 41.4 | 34.6 | 34.1 | 34.3 |
| MLS Bench | 48.3 | 49.9 | 46.2 | 42.8 | 40.4 |
| Kimi Code Bench 2.0(内部) | 72.9 | 76.9 | 64.8 | 71.7 | 64.2 |
| 智能体 | |||||
| GDPval-AA v2(Elo) | 1668 | 1760 | 1748 | 1600 | 1514 |
| BrowseComp | 91.2 | 88.0 | 90.4 | 84.3 | N/A |
| DeepSearchQA(F1) | 95.0 | 94.2 | N/A | 93.1 | N/A |
| Toolathlon-Verified | 73.2 | 77.9 | 74.9 | 76.2 | 59.9 |
| MCP Atlas | 84.2 | 84.7 | 83.6 | 83.6 | 82.6 |
| Automation Bench | 30.8 | 29.1 | 29.7 | 27.2 | 12.9 |
| Job Bench | 52.9 | 57.4 | 46.5 | 48.4 | 43.4 |
| AA-Briefcase(Elo) | 1548 | 1583 | 1495 | 1354 | 1260 |
| APEX-Agents | 41.0 | 43.3 | 39.9 | 39.4 | 35.6 |
| Office QA Pro | 63.3 | 69.9* | 63.2* | 63.9* | 41.4 |
| SpreadsheetBench 2 | 34.8 | 34.7* | 32.4* | 31.6* | 28.1 |
| DECK-Bench(内部) | 73.5 | 73.0 | 74.7 | 66.9 | 68.6 |
| 推理 & 知识 | |||||
| GPQA-Diamond | 93.5 | 92.6 | 94.1 | 91.0 | 91.2 |
| HLE-Full | 43.5 | 53.3 | 44.5 | 49.8* | N/A |
| HLE-Full w/ tools | 56.0 | 63.0 | 58.0 | 57.9* | N/A |
| 视觉 | |||||
| MMMU-Pro | 81.6 | 81.2 | 83.0 | 78.9 | N/A |
| MMMU-Pro w/ python | 83.4 | 86.5 | 84.6 | 82.7 | N/A |
| CharXiv (RQ) | 84.8 | 88.9 | 84.6 | 80.5 | N/A |
| CharXiv (RQ) w/ python | 91.3 | 93.5 | 89.1 | 89.9 | N/A |
| MathVision | 94.3 | 94.8 | 95.8 | 86.7 | N/A |
| MathVision w/ python | 97.8 | 98.6 | 97.8 | 97.1 | N/A |
| BabyVision w/ python | 85.7 | 90.5 | 88.9 | 81.2 | N/A |
| ZeroBench_main (pass@5) | 23.0 | 23.0 | 17.0 | 17.0 | N/A |
| ZeroBench_main w/ python (pass@5) | 41.0 | 46.0 | 35.0 | 34.0 | N/A |
| WorldVQA ForceAnswer | 51.0 | 56.7 | 41.8 | 39.1 | N/A |
| OmniDocBench | 91.1 | 89.8 | 85.8 | 87.9 | N/A |
| PerceptionBench | 58.5 | 57.2 | 59.7 | 47.2 | N/A |
所有 Kimi K3 结果均使用 max 推理强度。带星号(*)的数值是在与基础运行不同的条件下报告的,例如引自外部来源或使用了不同的测试框架。N/A 表示没有公布的分数。底色标记表示该行的领先结果。各基准测试的具体方法请参阅原始报告。来源:Kimi K3。
Kimi K3 与前沿模型的对比
汇总的基准测试表能说明的有限。为了在成本、编码质量和路由行为上做直接对比,我们在 DeepSWE 上让 Kimi K3 与领先的专有模型同台比拼:
常见问题
Kimi K3 是什么?Kimi K3 是 Moonshot AI 的旗舰模型,参数量 2.8 万亿,也是首个 3 万亿参数级别的开源模型,专为长周期编码、知识工作和推理而构建。
Kimi K3 是开源的吗?
是的。它以开放权重模型的形式发布,Together AI 正与 Moonshot 团队直接合作来提供该模型的服务。
Kimi K3 的上下文窗口有多大?
1M token(1,048,576),Together AI 完整支持,并提供自动上下文缓存。
Kimi K3 在 Together AI 上的价格是多少?
缓存命中的输入为每 1M token \$0.30,缓存未命中的输入为每 1M token \$3.00,输出为每 1M token \$15.00。
可以关闭 Kimi K3 的思考吗?
在 Together AI 上,你可以通过 reasoning={"enabled": False} 关闭思考,也可以把 reasoning_effort 设为 low、high 或 max 来调节推理深度。
Kimi K3 支持视觉吗?
支持。它具备原生视觉能力,每个请求可接受多张图像,只要整个请求体小于 100 MB。
Kimi K3 已登陆 Together AI。运行它,并将其投入生产。
让 K3 为你所用,从一次 API 调用开始。
- 运行 Kimi K3 推理:Together AI 上的 Kimi K3 API
- 开始用 API 构建:阅读文档