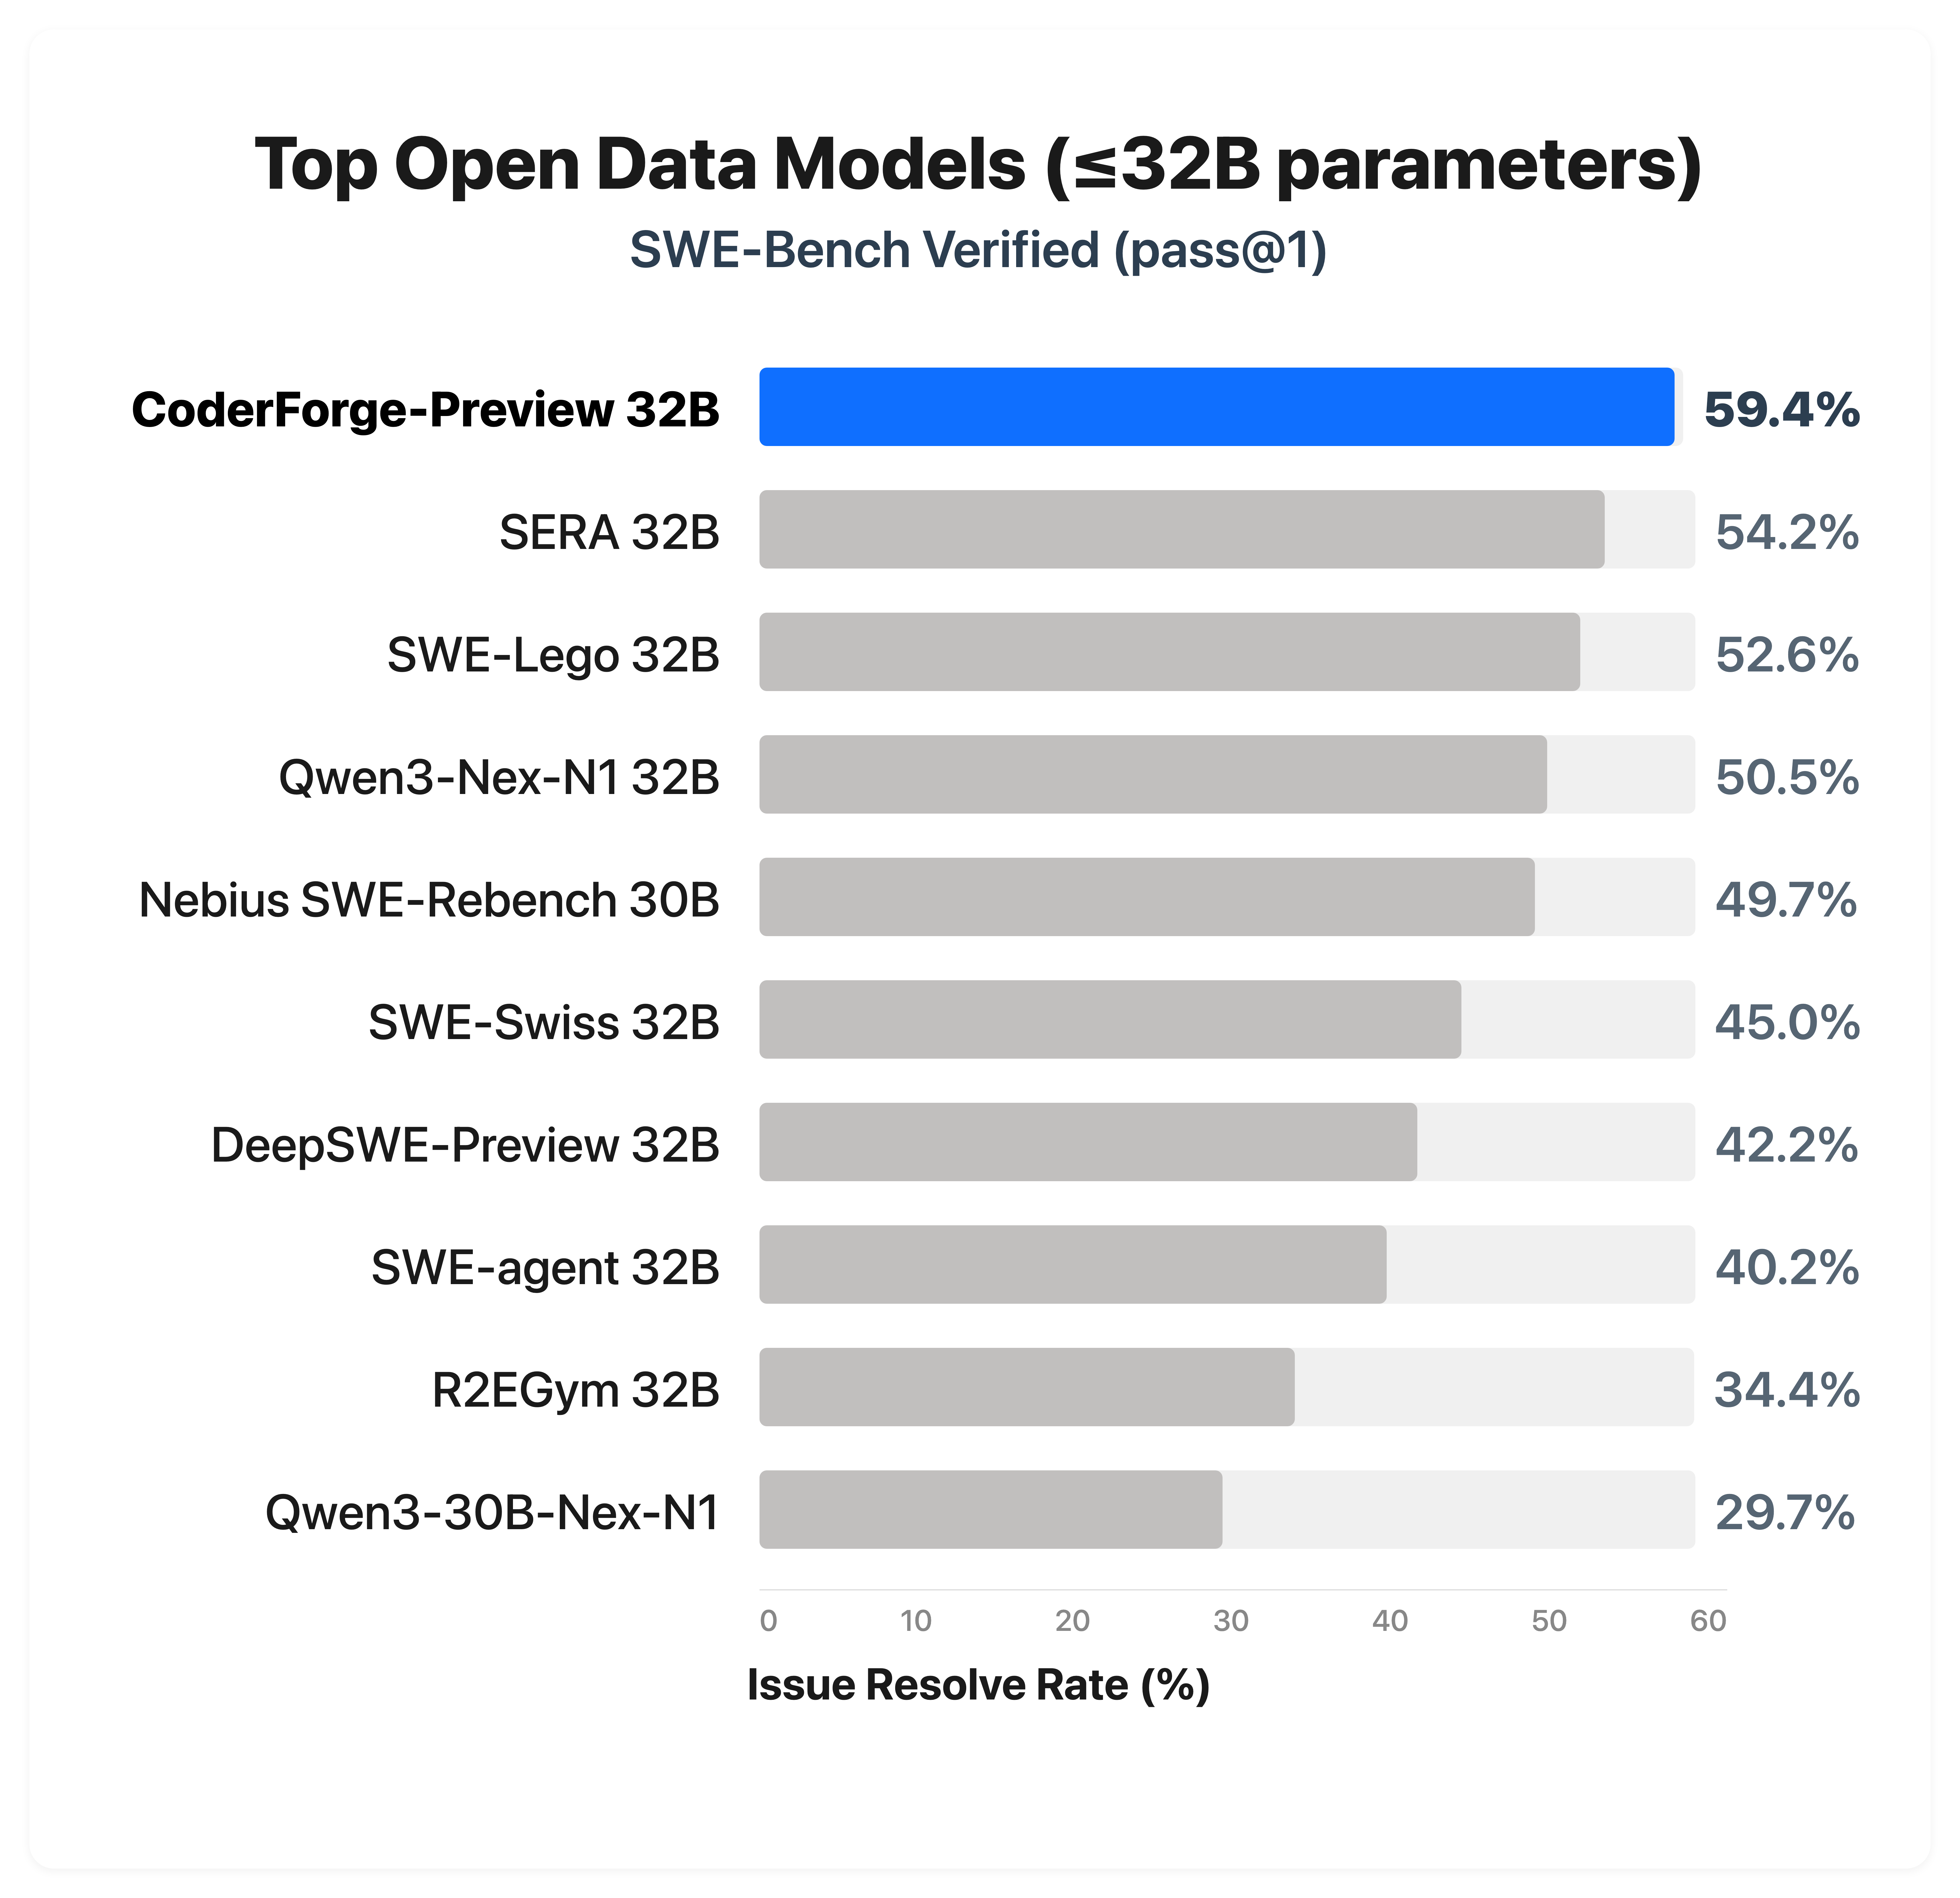
我们发布了 CoderForge-Preview——目前最大的开源、经测试验证的编码智能体数据集。用它微调 Qwen-3 32B 后,SWE-Bench Verified 成绩比基础模型提升 23.0%,达到 59.4%,在 ≤32B 参数范围内的开放数据模型中排名第一。
随着编码智能体的能力日益增强,研究界面临一个关键瓶颈:缺乏大规模、高质量的开放训练数据。专有模型不断进步,而开放权重的替代方案却因难以获得有效训练智能体所需的长上下文、经测试验证的轨迹而受到掣肘。
我们发布 CoderForge-Preview,这是迄今最大的开放编码智能体轨迹数据集——包含 25.8 万条经测试验证的轨迹(15.5 万条通过 | 10.3 万条失败),覆盖 1,655 个代码仓库中的 5.1 万个任务,同时分享我们用它训练 32B 和 4B 模型的结果。通过公开发布 CoderForge,我们希望推动整个开源 AI 社区的进展,让各地的研究者都能在我们的工作基础上构建、研究和改进。微调 Qwen-3 32B 后,在 SWE-Bench Verified [8] 上达到 59.4% 的 pass@1,在 ≤32B 参数范围内的开放数据模型中排名第一。
我们发布完整的轨迹数据集,以及 32B 模型的评估轨迹。
CoderForge-Preview 数据
我们使用 Qwen3-Coder-480B 从三个不同的任务来源生成智能体轨迹,并通过拒绝采样过滤掉未能通过测试的解答。这一流程产出了覆盖 5.1 万个任务的 25.8 万条长上下文轨迹(最长 128K 词元),我们从中保留 15.5 万条高质量、经测试验证的轨迹用于 SFT 训练。
任务来源
我们的任务来自三个来源:R2E-Gym [5]、SWE-Smith [6] 和 SWE-Rebench [7]:
表 1:任务数量为在我们的执行环境中有效的实例数。
| 来源 | 任务数 | 独立仓库数 |
|---|---|---|
| R2E-Gym | 4,216 | 9 |
| SWE-Smith | 37,221 | 124 |
| SWE-Rebench | 9,764 | 1,577 |
| 总计 | 51,201 | 1,655 |
设置
在智能体脚手架方面,我们把 OpenHands v0.52.1 脚手架 [4] 集成到 R2E-Gym [5] 数据生成框架中。它包含四个主要工具:bash 执行(execute_bash)、文件编辑(str_replace_editor)、记录思考(think)和任务完成(finish)。每个 Docker 评估环境中都预装了 OpenHands,使 LLM 智能体能够通过标准化的动作/观察接口与隔离的代码仓库交互。每个任务都在独立的 Docker 容器中执行,智能体在其中最多迭代 100 步,反复发出 bash 命令和文件编辑,最终生成补丁。
我们以 Qwen3-Coder-480B 作为数据生成的主力模型,temperature 为 0.7,top_p 为 0.8,最大新生成词元数为 32,768。为了增加成功轨迹的数量,我们为每个问题生成多条轨迹——R2E-Gym 和 SWE-Rebench 为 8 条,SWE-Smith 为 4 条。我们只保留最终补丁通过全部仓库测试的轨迹。为避免评估泄漏,我们排除了所有与 SWE-Bench Verified 样本具有相同(repository, base_commit)对或相同问题描述的任务。
与其他数据集的对比
表 2:CoderForge-Preview 与其他开放编码智能体数据集的对比。
| 数据集 | 教师模型 | 上下文长度 | 规模(总计) | 规模(过滤后) |
|---|---|---|---|---|
| R2E-Gym/R2EGym-SFT-Trajectories | Claude Sonnet 3.5 | 20000 | 3,231 | 3,231 |
| SWE-bench/SWE-smith-trajectories | Claude Sonnet 3.7 | 32768 | 49,897 | 21,513 |
| allenai/SERA [10] | GLM-4.6 | 32768 | 25,224 | 25,224 |
| nex-agi/agent-sft (agentic_code) [11] | DeepSeek-V3.1-Nex-N1 | 128000 | 24,796 | 24,796 |
| nebius/SWE-rebench-openhands-trajectories [12] | Qwen3-Coder-480B | 128000 | 67,074 | 32,161 |
| CoderForge-Preview 数据 | Qwen3-Coder-480B | 128000 | 258,134 | 155,144 |
在同类发布中,CoderForge-Preview 数据是规模最大、表现最好的编码智能体轨迹数据集。它在 128K 上下文长度下共有 258,134 条轨迹,其中 155,144 条成功,在规模和长上下文覆盖上都大幅超过此前的数据集。
按任务来源统计的轨迹成功率
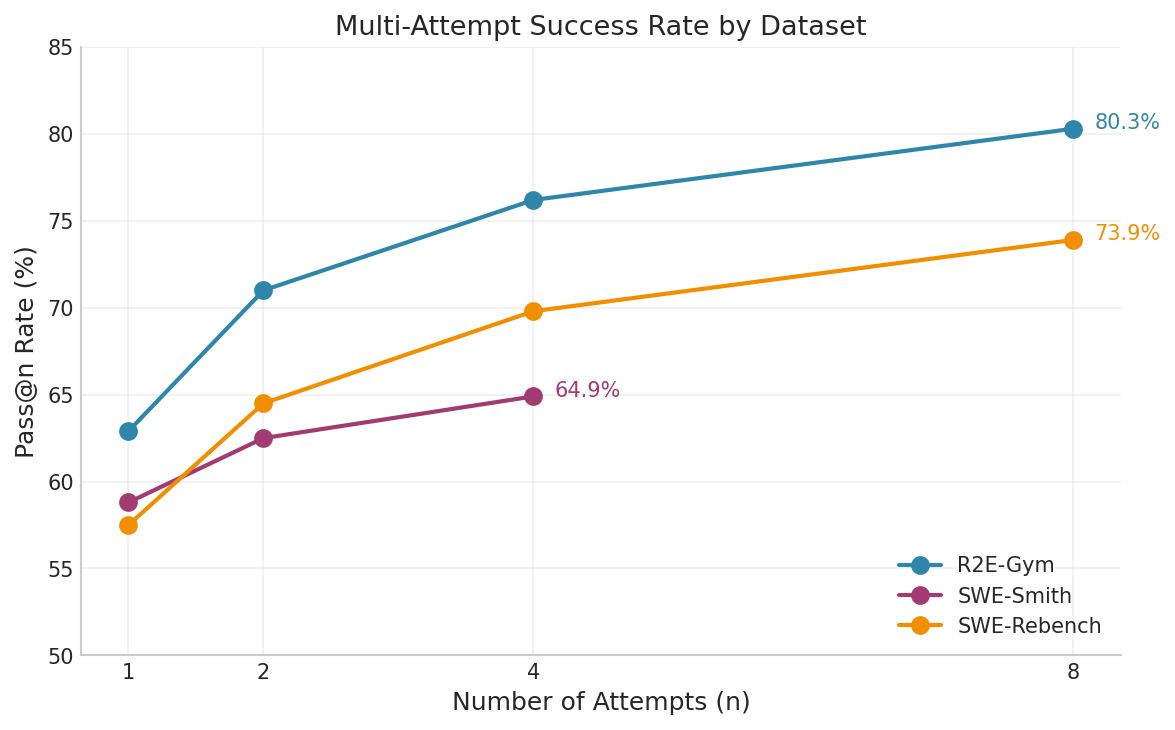
对每条轨迹,我们运行其任务附带的相关测试,检查模型是否解决了问题。R2E-Gym 任务的解决率始终最高,从 Pass@1 的 62.9% 升至 Pass@8 的 80.3%。SWE-Rebench 同样从多次尝试采样中获益显著,到 Pass@8 时从 57.5% 提升到 73.9%。SWE-Smith 的提升较为有限,从 Pass@1 的 58.8% 增至 Pass@4 的 64.9%。总体来看,这一趋势说明多样本生成能有效提高成功轨迹的产出,随着尝试次数增加,收益递减但始终存在。
最终的任务来源分布
我们根据轨迹是否成功解决任务对生成的轨迹进行过滤,得到如下所示的任务分布。在我们的 SFT 实验中,只使用成功的轨迹进行训练。
| 任务来源 | 生成的轨迹数 | 生成的轨迹数(reward = 1.0) |
|---|---|---|
| R2E-Gym | 32,964 | 20,904 |
| SWE-Smith | 148,001 | 89,501 |
| SWE-Rebench | 77,169 | 44,739 |
| 总计 | 258,134 | 155,144 |
轨迹特征
数据生成成本
表 3:各任务来源的数据生成成本与效率指标。
| 来源 | # Completions API 调用数 | 提示词元数 | 输出词元数 | 平均输出词元数 | 缓存命中率 |
|---|---|---|---|---|---|
| R2E-Gym | 2.18M | 59B | 404M | 185.4 | 96.64% |
| SWE-Smith | 8.47M | 238B | 1,544M | 182.4 | 90.15% |
| SWE-Rebench | 4.99M | 155B | 965M | 193.3 | 88.64% |
| 总计 | 15.64M | 452B | 2.91B | 186.3 | 90.48% |
高效的长上下文推理和激进的提示词缓存使大规模数据生成成为可能。在 R2E-Gym、SWE-Smith 和 SWE-Rebench 上,我们共发出 1564 万次 API 补全调用,处理了 4520 亿个提示词元,生成了 29.1 亿个输出词元,整体缓存命中率约为 90%。按每百万缓存词元 0.25 的定价模型计算,以及 130k。
轨迹分析
表 4:各数据来源的轨迹长度分布与训练词元总数。
| 来源 | 中位长度 | 平均长度 | P99 长度 | 训练词元总数 |
|---|---|---|---|---|
| R2E-Gym | 39,599 | 42,149 | 83,549 | 0.97B |
| SWE-Smith | 36,008 | 39,313 | 88,101 | 3.65B |
| SWE-Rebench | 41,996 | 45,236 | 99,391 | 2.08B |
| 总计 | 38,052 | 41,398 | 91,150 | 6.70B |
该表展示了各数据来源所生成智能体轨迹的长度分布。轨迹长度的中位数在 36K–42K 词元之间,平均长度约 41K 词元,P99 长度接近 100K 词元,凸显了数据的长上下文特性。合并后的数据集共包含 67.0 亿个训练词元。
表 5:各数据来源中成功与失败轨迹的平均智能体步数。
| 来源 | 平均步数(成功) | 平均步数(失败) |
|---|---|---|
| R2E-Gym | 55.7 | 65.6 |
| SWE-Smith | 48.3 | 61.0 |
| SWE-Rebench | 56.2 | 72.0 |
我们比较了各数据来源中成功轨迹与失败轨迹的平均智能体步数。在所有情况下,失败轨迹所需的步数都明显更多,平均比成功轨迹多 18–28%。通过只在成功轨迹上训练,我们希望推动模型走向高效的任务解决和简洁的决策,而不是从冗长且无效的步骤序列中学习。
许可证过滤
为确保数据集能够被负责任地使用,我们对每个任务所引用的确切提交(commit)下的每个仓库进行了全面的许可证审计。我们在特定的 commit SHA 下获取每个仓库的 LICENSE 文件,并使用 scancode-toolkit 对其进行识别,这是 Linux 基金会和 SPDX 项目使用的行业标准许可证检测引擎。
我们只保留来自采用宽松开源许可证的仓库的轨迹:
| 许可证 | SPDX 标识符 |
|---|---|
| MIT License | MIT |
| BSD 3-Clause | BSD-3-Clause |
| Apache License 2.0 | Apache-2.0 |
| BSD License | BSD |
| BSD 2-Clause | BSD-2-Clause |
| Historical Permission Notice and Disclaimer | HPND |
| ISC License | ISC |
| PostgreSQL License | PostgreSQL |
| Python Software Foundation License | PSF-2.0 |
| Creative Commons Zero 1.0 | CC0-1.0 |
| MIT No Attribution | MIT-0 |
| MIT-CMU License | MIT-CMU |
| BSD 4-Clause | BSD-4-Clause |
| 双重许可:MIT 与 Apache-2.0 | MIT AND Apache-2.0 |
| 双重许可:Apache-2.0 与 BSD-3-Clause | Apache-2.0 AND BSD-3-Clause |
| 双重许可:BSD-3-Clause 与 MIT | BSD-3-Clause AND MIT |
CoderForge-Preview 训练实验
训练设置
我们选择稠密模型 Qwen3-32B [1] 作为微调的基础模型。
为支持 128K 长度序列的高效训练,我们通过 Ulysses [2] 采用序列并行,对序列维度进行切分,并用优化过的 all-to-all 通信来计算注意力。此外,由于数据集中轨迹长度不一,我们使用多重打包(multi-packing)把多条较短的轨迹打包进同一训练序列,并通过感知边界的掩码防止样本间的注意力相互污染 [3]。
我们采用词元级损失函数,在 FSDP & 序列并行的所有 GPU 上聚合整个批次中所有词元的梯度。这意味着每个词元对总损失的贡献都按批次内的词元总数做了归一化,使长序列和短序列得到一致的加权。
给定:rank 上微批次的平均交叉熵损失,:rank 上微批次中的有效词元数,:所有 rank 和微批次上的有效词元总数,归一化后的损失计算如下:
我们在 8 个节点(64 块 H100 GPU)上训练 Qwen3-32B 模型,采用 FSDP2(分片大小 = 8)、Ulysses 序列并行(大小 = 8),使用 BF16、梯度检查点和 FlashAttention-2。为了最大化训练吞吐量,我们使用顺序打包来充分利用 128K 上下文窗口,确保长度各异的序列之间填充浪费最小。详细的长度分析如下:
表 6:采用 multipack 采样时的训练序列长度分布(128K 上下文窗口)。
| 指标 | 数值 | 解读 |
|---|---|---|
| 平均长度 | 104,891 词元 | 利用了约 82% 的 128K |
| 中位长度 | 105,274 词元 | 分布对称 |
| 标准差 | 5,906 词元 | 方差低(变异系数约 5.6%) |
| 最小值 / 最大值 | 77,501 / 123,975 | 范围覆盖良好 |
聊天模板
我们采用 Qwen Coder 的聊天模板,其 XML 格式的工具调用更适合 LLM。我们还在 Huggingface 上数据集的 trajectories-tokenized_qwencoder 子集中发布了带损失掩码的已分词轨迹。
评估
主要结果
我们在 SWE-bench Verified 上评估模型,这是一个由 500 个真实 GitHub issue 组成的精选子集,用于测试端到端的软件工程能力。我们最好的模型在第 3.13 个 epoch 时达到 59.4% 的 pass@1 和 78.56% 的 pass@16,既展现了出色的单次尝试准确率,也显示出多次采样下优异的覆盖率。我们的训练数据 CoderForge-Preview 数据融合了多个来源的轨迹,以最大化多样性和覆盖面。
| 模型 | SWE-Bench-Verified(pass@1) | SWE-Bench-Verified(pass@16) |
|---|---|---|
| CoderForge-Preview-32B | 59.4% | 78.56% |
| CoderForge-Preview-4B | 43.0% | - |
重复惩罚
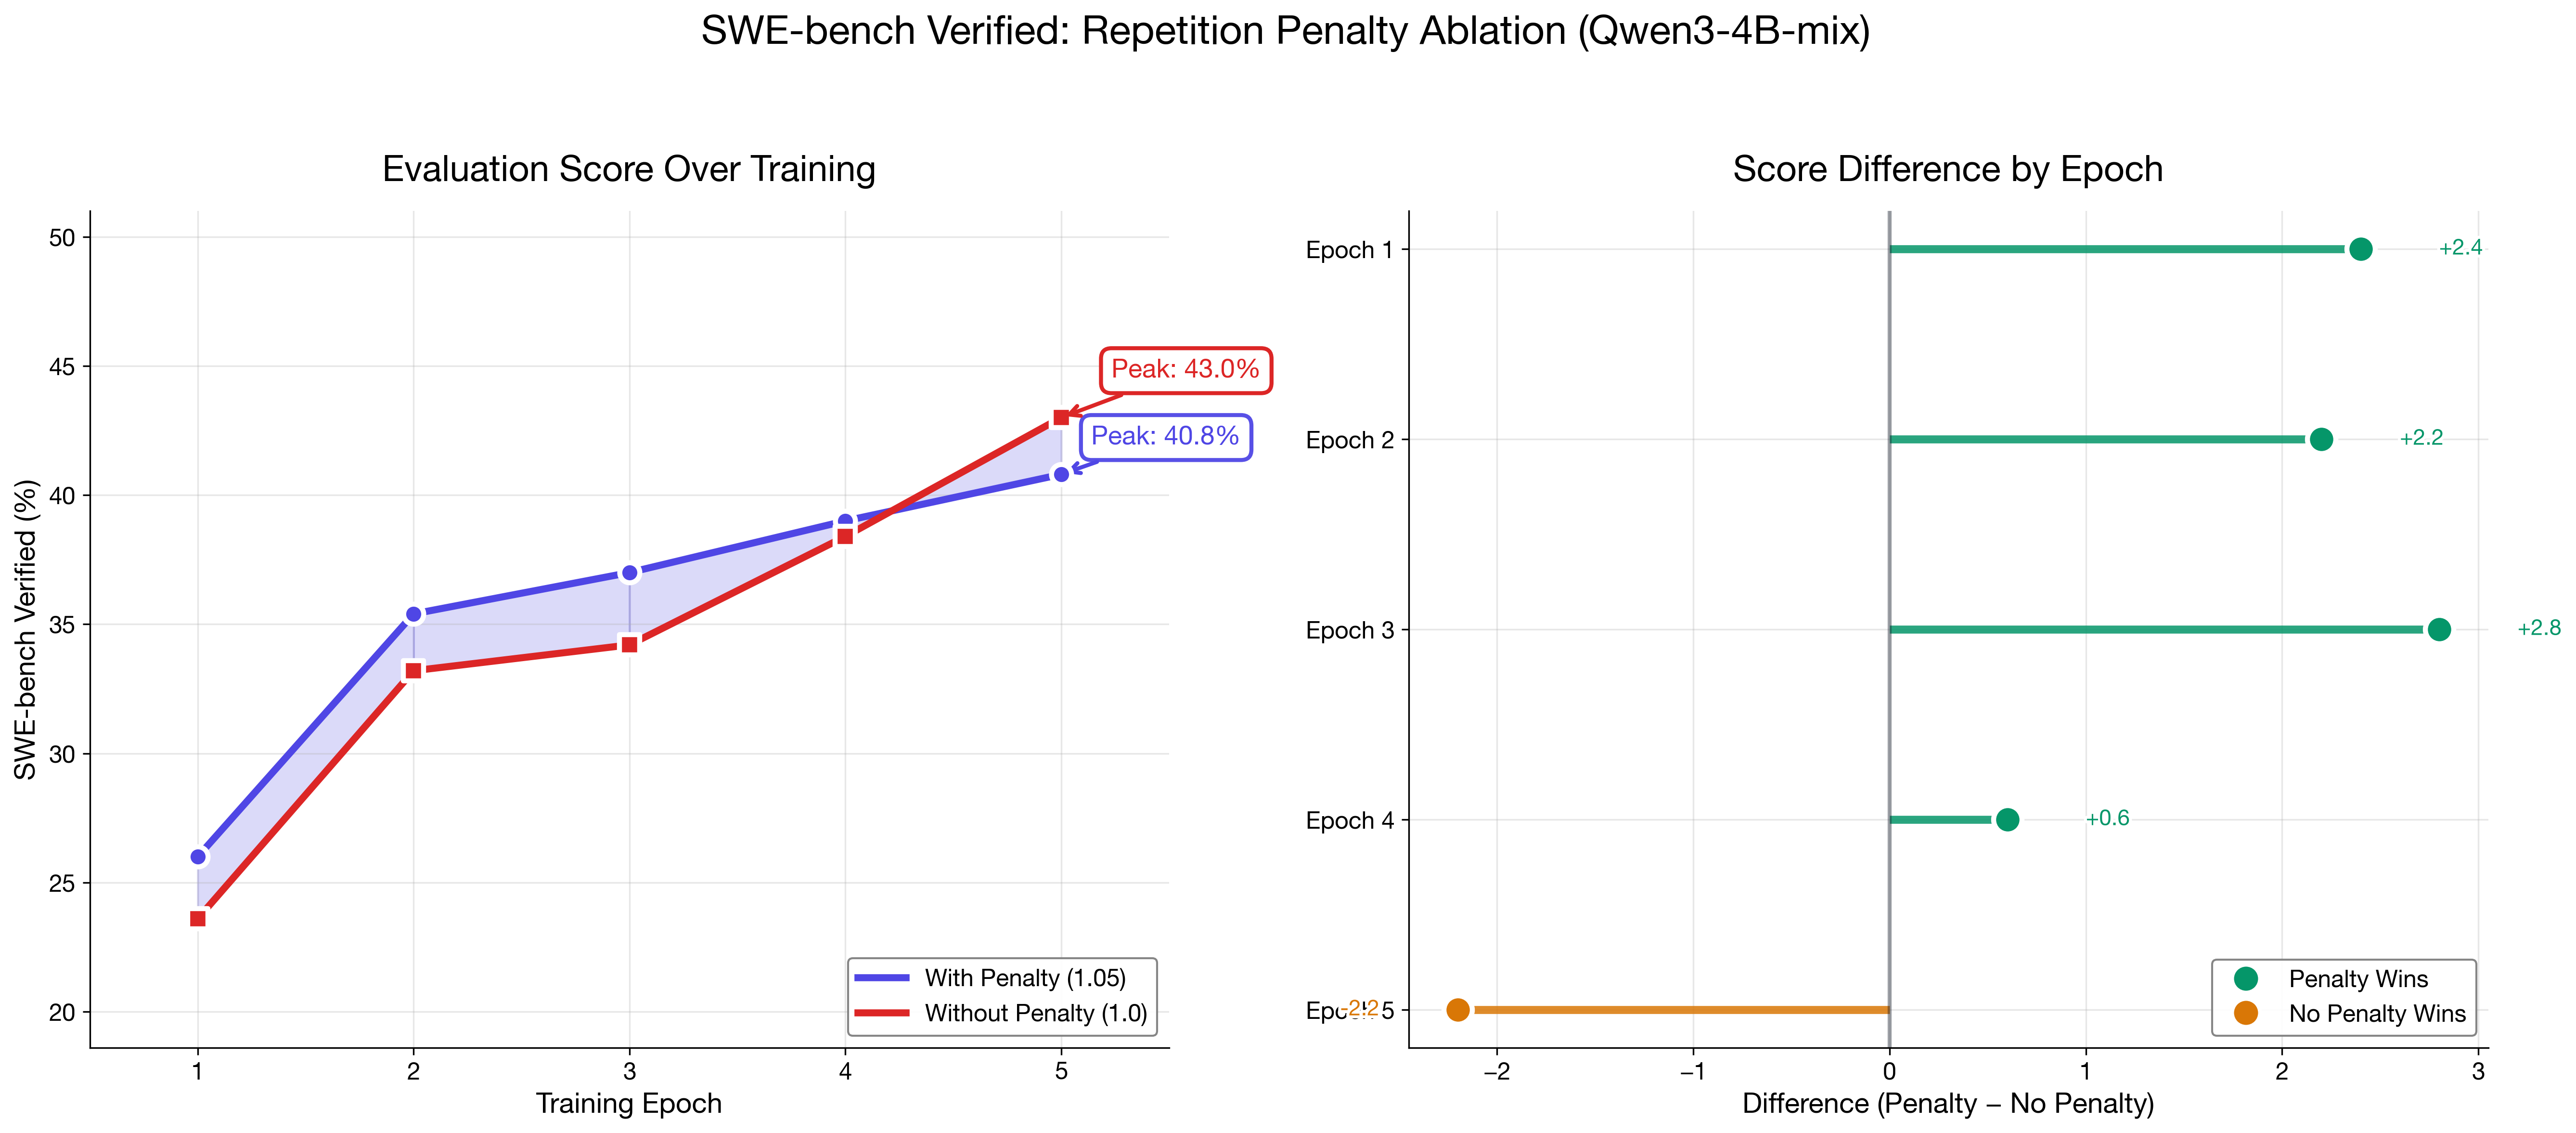
在训练早期,我们注意到大量 str_replace_editor 工具调用失败,原因是模型重复了它想要替换的字符串。我们研究了轻度的重复惩罚能否在不损害精确代码编辑的前提下抑制退化循环,结果如下:
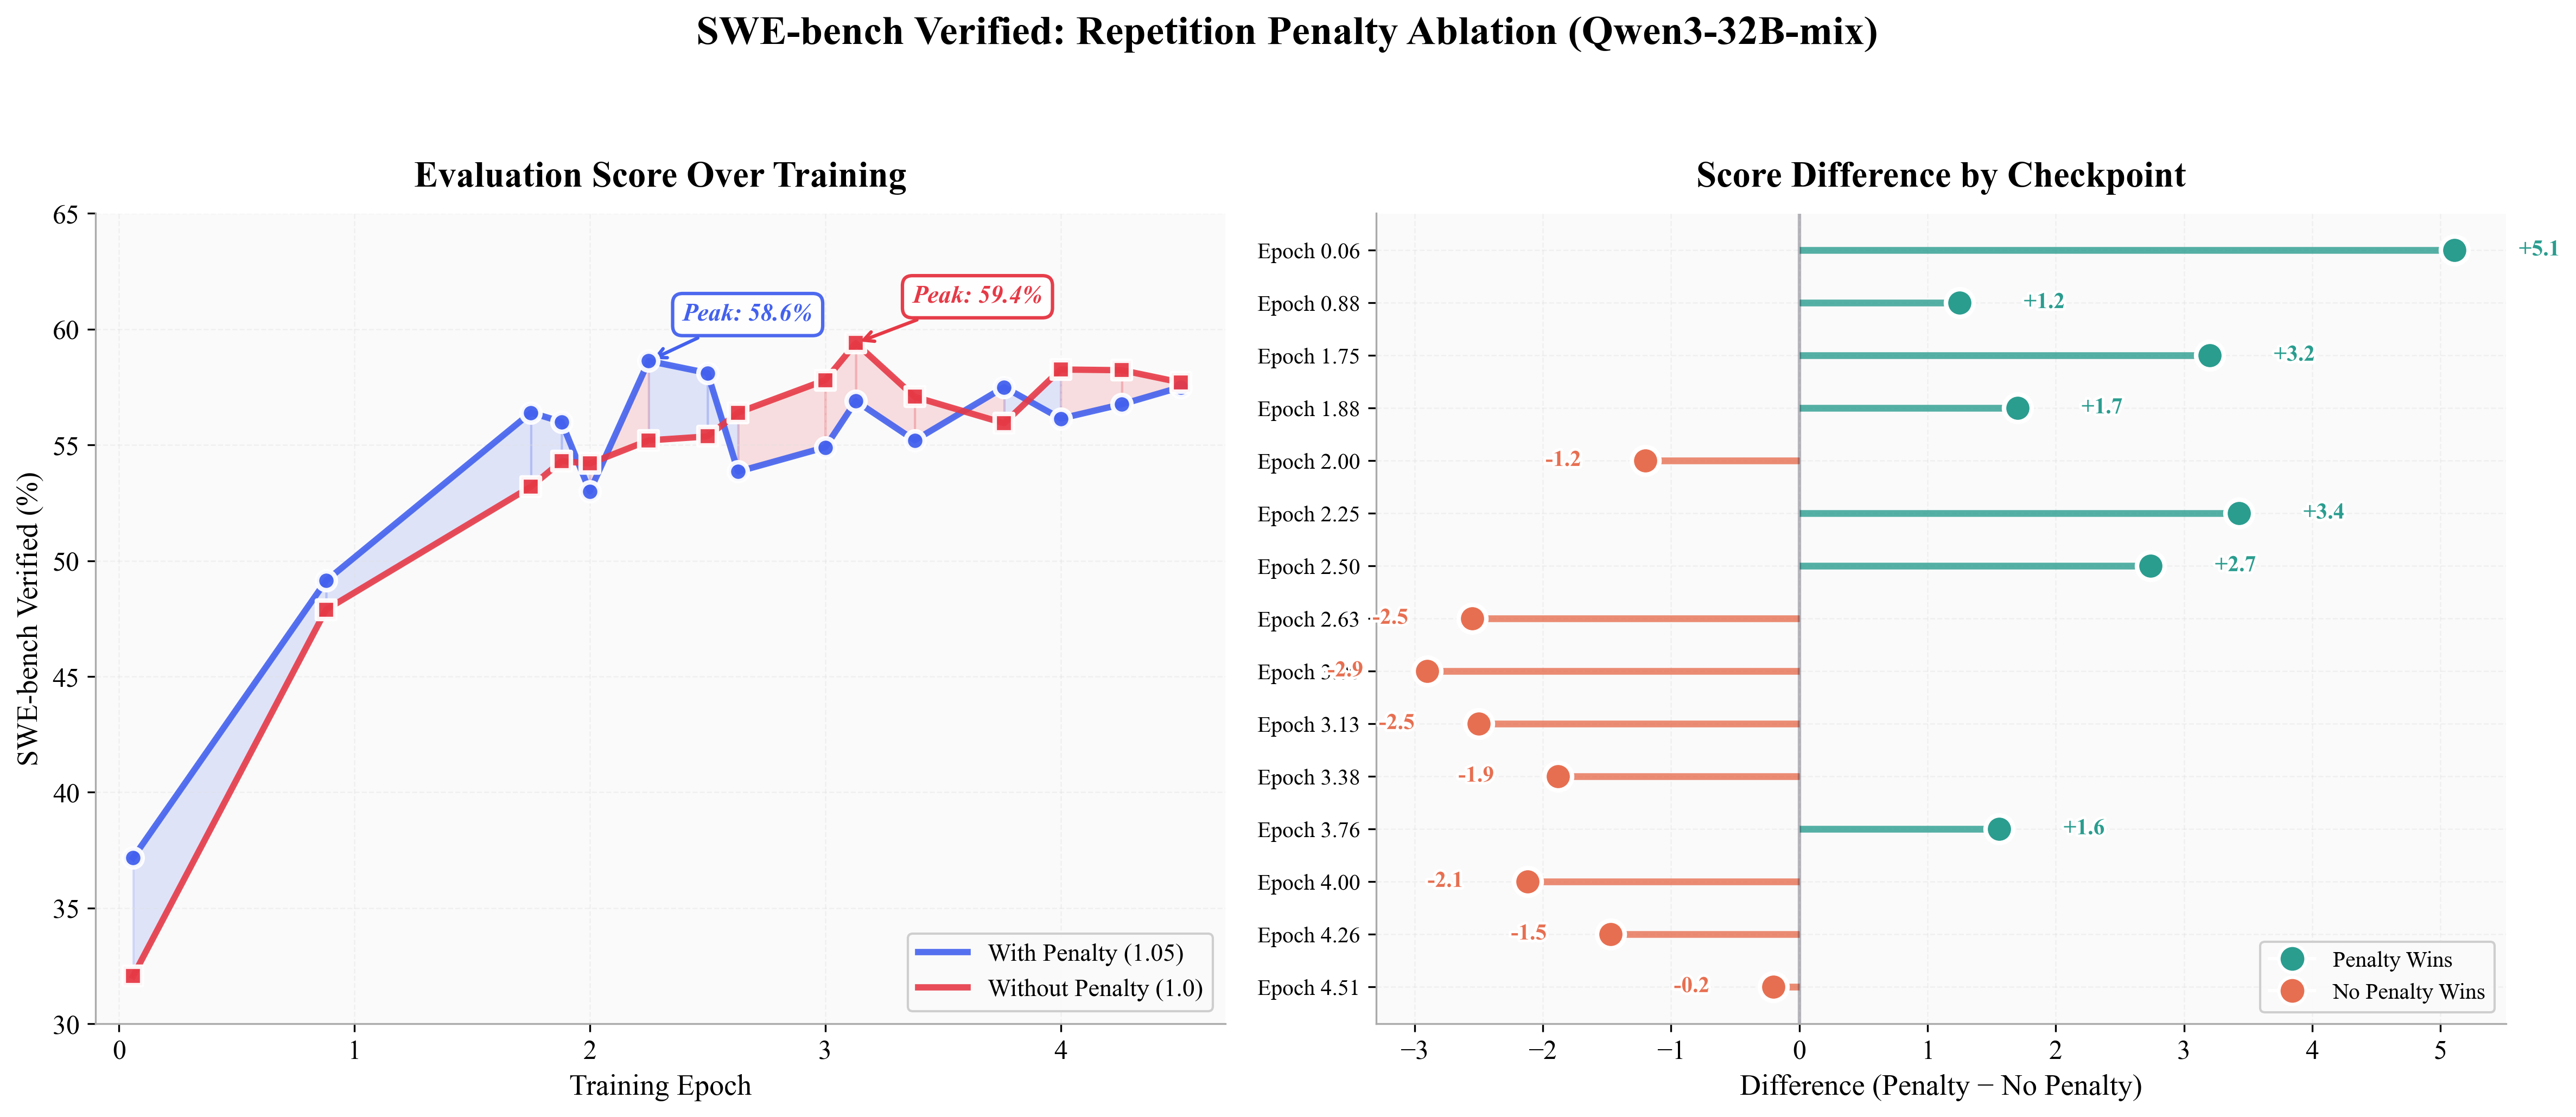
结论:对于生产部署,我们建议对后期 epoch 的检查点不使用重复惩罚。不过,对于提前停止训练的模型,轻度惩罚可以起到有益的正则化作用。
缩小规模的实验
为了检验数据集在较小规模上是否也能提供学习信号,我们微调了 Qwen3‑4B。SWE-bench Verified 的结果显示,在 5 个 epoch 内学习进展明显:4B 模型的得分提升到 43.0%(第 5 个 epoch)。
重复惩罚的消融实验显示出与 32B 设置类似的趋势:它在早期(第 1–3 个 epoch)有帮助,但对表现最佳的后期检查点没有益处。
4B(43.0%)与 32B(59.4%)之间的峰值性能差距证实,模型容量对复杂的智能体任务很重要;而持续向上的改进轨迹也验证了我们的训练数据在两种规模上都提供了真实的信号。
评估轨迹发布
我们发布 CoderForge-Preview-32B 的评估轨迹。
我们的设置如下:
- 脚手架:OpenHands v0.52.1
- 采样参数:
- temperature: 0.7
- top_p: 0.8
- max_tokens: 32768
- max_iterations: 100
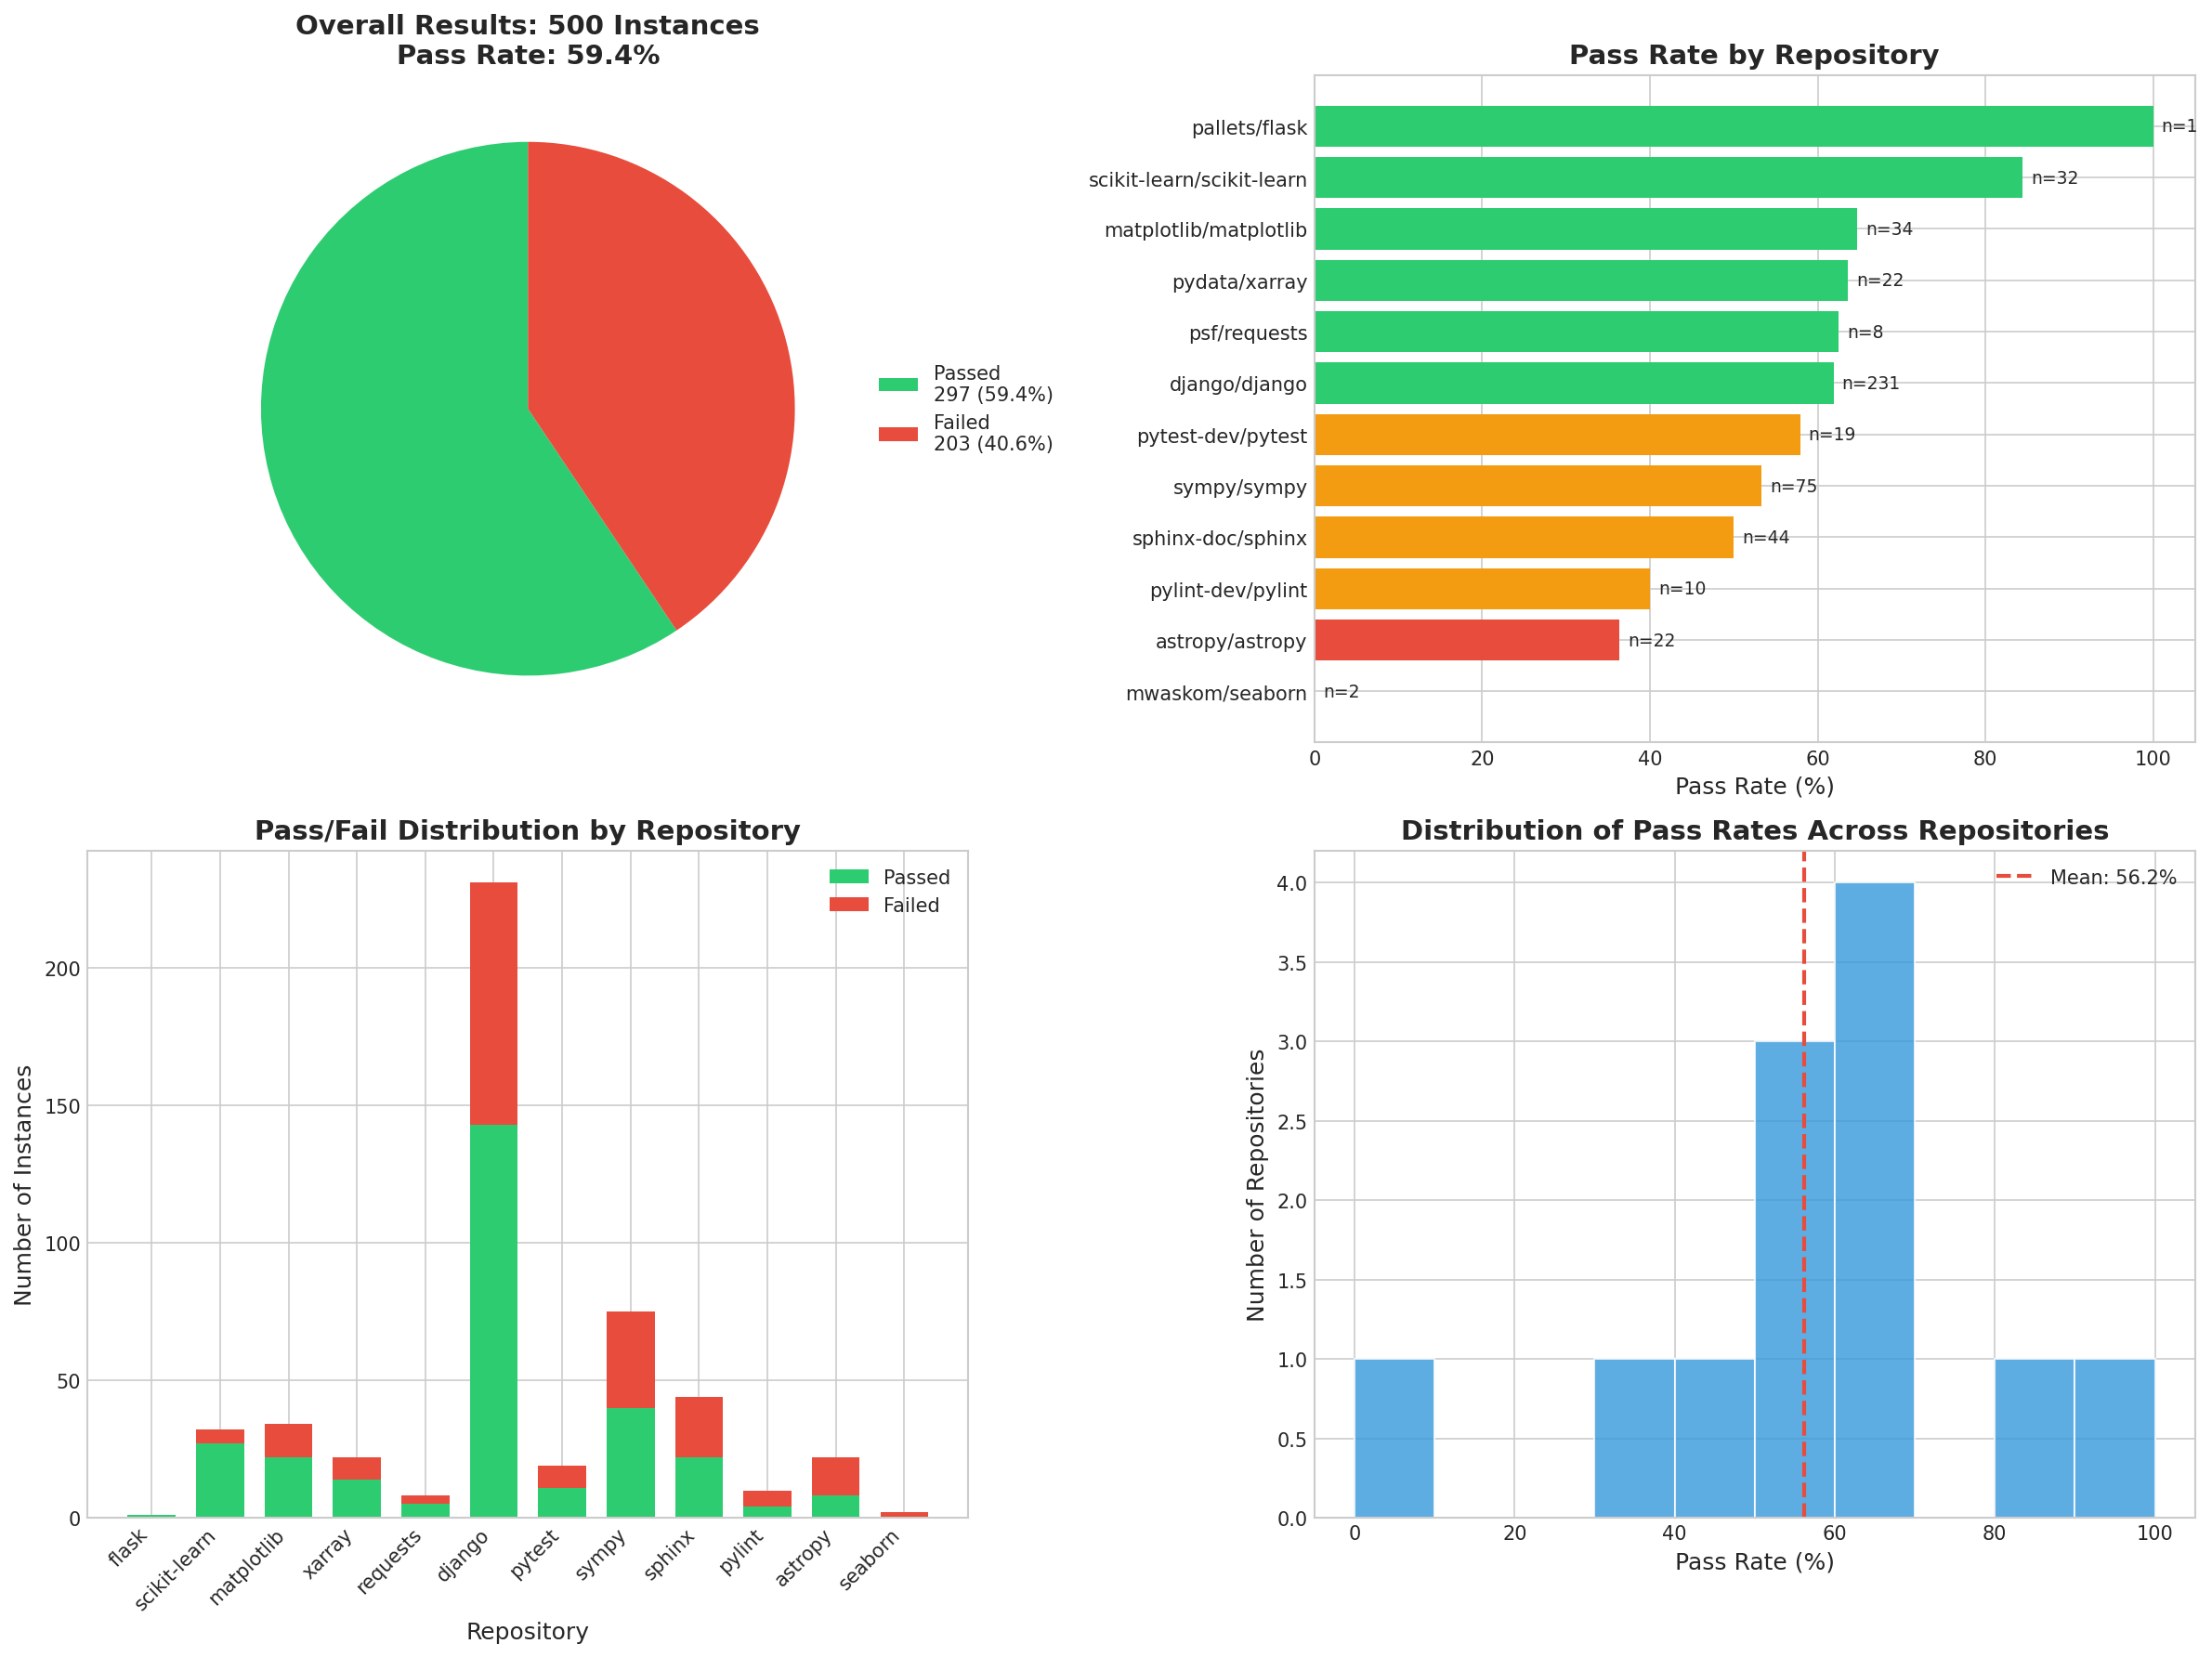
表现因仓库而异。排除样本量极小的仓库(例如 n<5)后,scikit‑learn 的解决率最高(84.4%),其次是 matplotlib(64.7%)和 xarray(63.6%)。对于 Django(n=231,占基准测试的 46%),模型解决了 61.9% 的实例。一些较低的比率(例如 seaborn)基于极小的 n,解读时应当谨慎
评估提示词模板
无论是数据生成还是评估,我们都采用 OpenHands SWE-Bench 模板:
<uploaded_files>
/workspace/{{ workspace_dir_name }}
</uploaded_files>

I've uploaded a python code repository in the directory {{ workspace_dir_name }}. Consider the following issue description:

<issue_description>
{{ instance.problem_statement }}
</issue_description>

Can you help me implement the necessary changes to the repository so that the requirements specified in the <issue_description> are met?
I've already taken care of all changes to any of the test files described in the <issue_description>. This means you DON'T have to modify the testing logic or any of the tests in any way!
Also the development Python environment is already set up for you (i.e., all dependencies already installed), so you don't need to install other packages.
Your task is to make the minimal changes to non-test files in the /workspace/{{ workspace_dir_name }} directory to ensure the <issue_description> is satisfied.

Follow these phases to resolve the issue:

Phase 1. READING: read the problem and reword it in clearer terms
   1.1 If there are code or config snippets. Express in words any best practices or conventions in them.
   1.2 Hightlight message errors, method names, variables, file names, stack traces, and technical details.
   1.3 Explain the problem in clear terms.
   1.4 Enumerate the steps to reproduce the problem.
   1.5 Hightlight any best practices to take into account when testing and fixing the issue

Phase 2. RUNNING: install and run the tests on the repository
   2.1 Follow the readme
   2.2 Install the environment and anything needed
   2.2 Iterate and figure out how to run the tests

Phase 3. EXPLORATION: find the files that are related to the problem and possible solutions
   3.1 Use `grep` to search for relevant methods, classes, keywords and error messages.
   3.2 Identify all files related to the problem statement.
   3.3 Propose the methods and files to fix the issue and explain why.
   3.4 From the possible file locations, select the most likely location to fix the issue.

Phase 4. TEST CREATION: before implementing any fix, create a script to reproduce and verify the issue.
   4.1 Look at existing test files in the repository to understand the test format/structure.
   4.2 Create a minimal reproduction script that reproduces the located issue.
   4.3 Run the reproduction script to confirm you are reproducing the issue.
   4.4 Adjust the reproduction script as necessary.

Phase 5. FIX ANALYSIS: state clearly the problem and how to fix it
   5.1 State clearly what the problem is.
   5.2 State clearly where the problem is located.
   5.3 State clearly how the test reproduces the issue.
   5.4 State clearly the best practices to take into account in the fix.
   5.5 State clearly how to fix the problem.

Phase 6. FIX IMPLEMENTATION: Edit the source code to implement your chosen solution.
   6.1 Make minimal, focused changes to fix the issue.

Phase 7. VERIFICATION: Test your implementation thoroughly.
   7.1 Run your reproduction script to verify the fix works.
   7.2 Add edge cases to your test script to ensure comprehensive coverage.
   7.3 Run existing tests related to the modified code to ensure you haven't broken anything.

8. FINAL REVIEW: Carefully re-read the problem description and compare your changes with the base commit {{ instance.base_commit }}.
   8.1 Ensure you've fully addressed all requirements.
   8.2 Run any tests in the repository related to:
     8.2.1 The issue you are fixing
     8.2.2 The files you modified
     8.2.3 The functions you changed
   8.3 If any tests fail, revise your implementation until all tests pass

Be thorough in your exploration, testing, and reasoning. It's fine if your thinking process is lengthy - quality and completeness are more important than brevity.
局限性
数据:
- 对不同脚手架的适应性:我们所有数据都用同一个脚手架和同一组工具生成,没有做排列组合,因此用这些数据做 SFT 的模型在搭配不同的脚手架、工具和提示词模板时,表现可能更差。
- 任务范围:由于我们的数据来源主要集中在修复 bug,用这些数据做 SFT 的模型在此范围之外的任务(如功能实现)上能力可能较弱。
- 用户交互:真实场景中使用编码智能体,大多涉及用户的介入以及与智能体的协作,即在整个轨迹过程中而不仅仅是开头发送用户消息。目前,包括我们在内的开放编码智能体数据集都缺少这类交互。因此,仅用这些数据做 SFT 的模型在交互式场景中可能表现不佳。
训练:
- 模型规模探索有限:受资源所限,我们只训练了两种规模。探索更大的模型很可能带来进一步提升。
- 超参数调优极少:受资源所限,我们使用了固定的训练配置(学习率 1e-5、余弦调度、128K 上下文),没有进行大量超参数搜索。系统地调整学习率、批大小、预热步数和损失权重,有可能改善收敛性和最终性能。
评估:
- 本次发布中,我们主要使用标准的 SWE-Bench-Verified 进行评估,而它所提供信号的质量最近引发了大量讨论。在下一个迭代中,我们将在更多编码和终端智能体基准测试上进行评估。
结论
在这项工作中,我们专注于大规模的智能体数据生成:从开源项目中汇集了 5.1 万个不同的任务,并生成长程、多步骤的监督微调(SFT)轨迹。我们的结果表明,简单的数据生成流水线加上纯 SFT 训练,就能显著提升智能体的编码性能。
展望未来,我们计划进一步扩大数据生成规模,使用不同的脚手架、工具和排列组合,并训练更大的模型,以更好地了解扩展的上限。此外,我们打算遵循 DeepSWE [9] 的训练范式,在微调后的模型之上应用智能体强化学习,以推动性能进一步提升。
BibTeX 引用
@misc{CoderForge2026,
  title        = {CoderForge-Preview: SOTA Open Dataset for Training Efficient Agents},
  author       = {Ariyak, Alpay and Zhang, Junda and Wang, Junxiong and Zhu, Shang and Bianchi, Federico and Srivastava, Sanjana and Panda, Ashwinee and Bharti, Siddhant and Xu, Chenfeng and Heo, John and Wu, Xiaoxia Shirley and Zou, James and Liang, Percy and Song, Leon and Zhang, Ce and Athiwaratkun, Ben and Zhou, Zhongzhu and Wu, Qingyang},
  year         = {2026},
  month        = feb,
  publisher    = {Together AI Blog},
  url          = {https://www.together.ai/blog/coderforge-preview},
  note         = {Project core leads: Alpay Ariyak; Zhongzhu Zhou; Qingyang Wu}
}
参考文献
[1] Qwen Team. "Qwen3-32B." Hugging Face Model Card (2025). https://huggingface.co/Qwen/Qwen3-32B
[2] Jacobs, Sam Ade, et al. "DeepSpeed Ulysses: System optimizations for enabling training of extreme long sequence transformer models." arXiv preprint arXiv:2309.14509 (2023).
[3] imoneoi. "Multipack Sampler: Padding-free distributed training of LLMs." GitHub repository (2024). https://github.com/imoneoi/multipack_sampler
[4] Wang, Xingyao, et al. "OpenHands: An open platform for AI software developers as generalist agents." arXiv preprint arXiv:2407.16741 (2024).
[5] Jain, Naman, et al. "R2E-Gym: Procedural environments and hybrid verifiers for scaling open-weights SWE agents." arXiv preprint arXiv:2504.07164 (2025).
[6] Yang, John, et al. "SWE-smith: Scaling data for software engineering agents." arXiv preprint arXiv:2504.21798 (2025).
[7] Badertdinov, Ibragim, et al. "SWE-rebench: An automated pipeline for task collection and decontaminated evaluation of software engineering agents." arXiv preprint arXiv:2505.20411 (2025).
[8] Jimenez, Carlos E., et al. "SWE-bench: Can language models resolve real-world GitHub issues?" ICLR 2024, arXiv preprint arXiv:2310.06770 (2024).
[9] Luo, Michael, et al. "DeepSWE: Training a state-of-the-art coding agent from scratch by scaling RL." TogetherAI/Agentica Blog (2025).
[10] Shen, Ethan, et al. "SERA: Soft-Verified Efficient Repository Agents." arXiv preprint arXiv:2601.20789 (2026). https://arxiv.org/abs/2601.20789
[11] Nex-AGI Team. "Nex-N1: Agentic Models Trained via a Unified Ecosystem for Large-Scale Environment Construction." arXiv preprint arXiv:2512.04987 (2025). https://github.com/nex-agi/Nex-N1
[12] Trofimova, Maria, et al. "OpenHands Trajectories with Qwen3-Coder-480B-A35B-Instruct." Nebius Blog (2025). https://nebius.com/blog/posts/openhands-trajectories-with-qwen3-coder-480b